Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
Announcing Ray 2.4.0: Infrastructure for LLM training, tuning ...
LLM training and inference — Ray 2.59.0
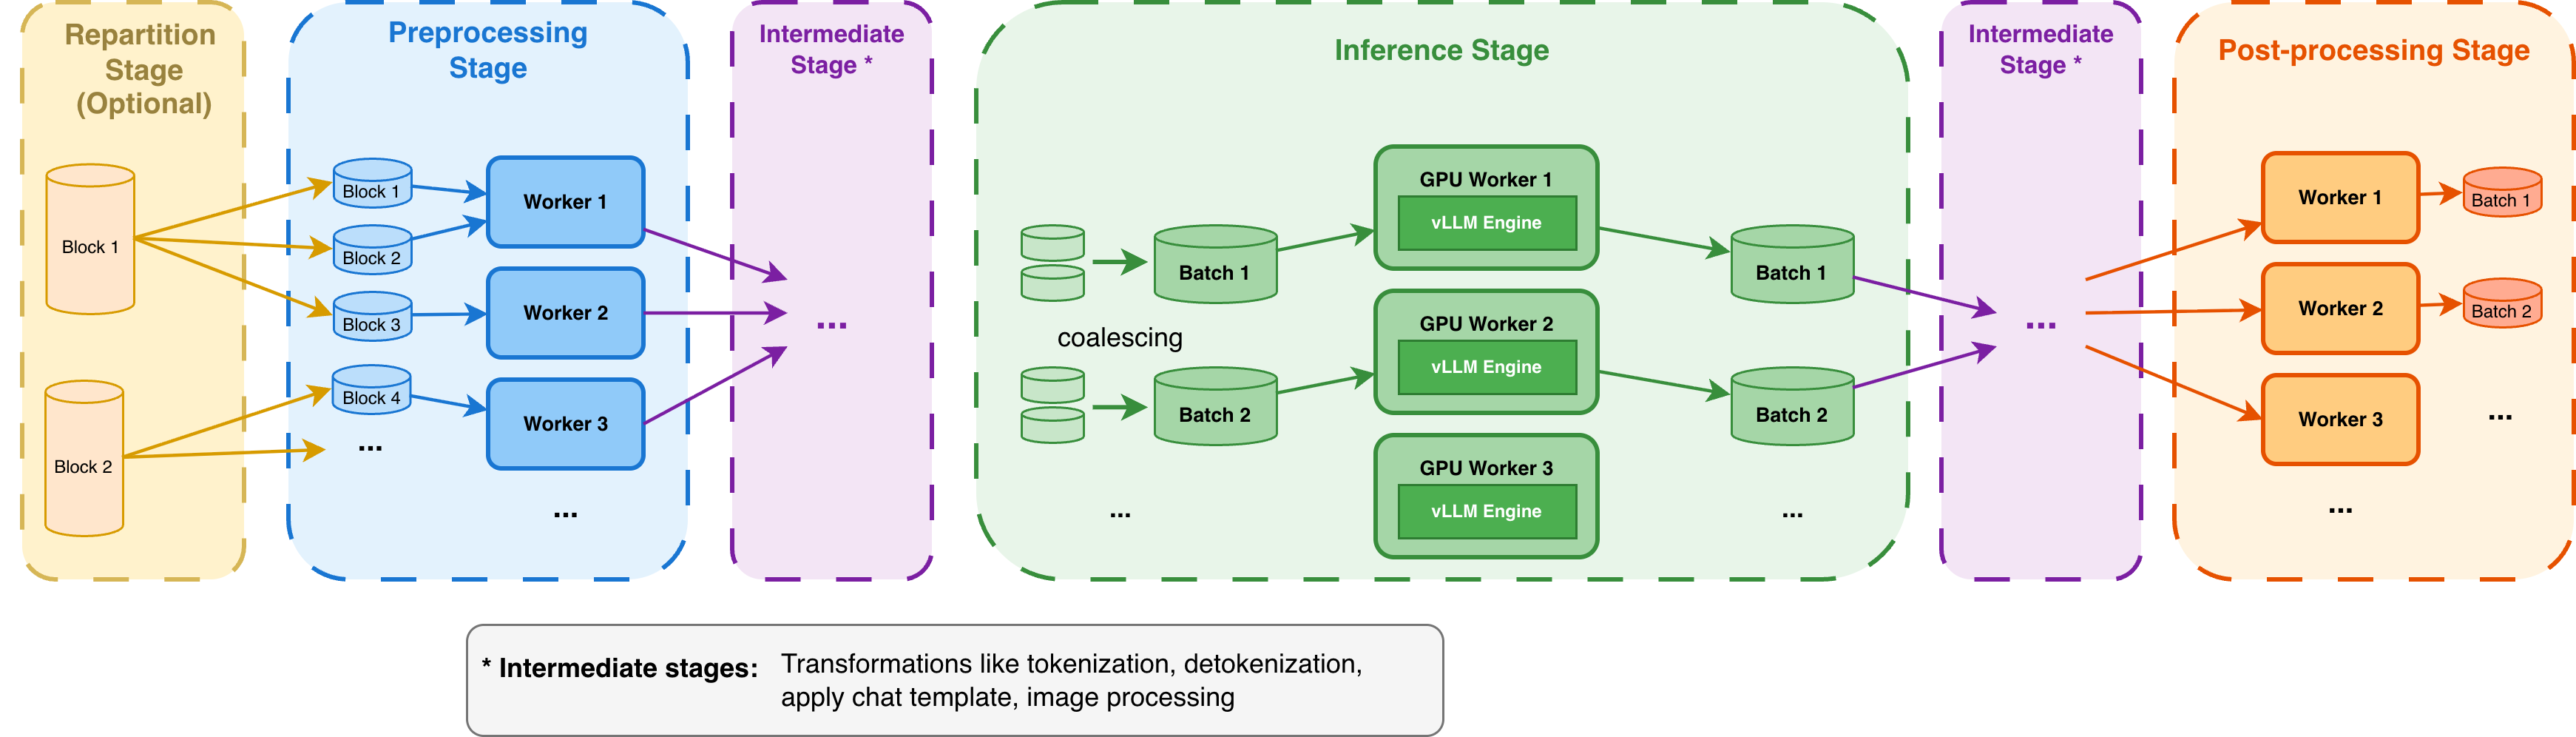
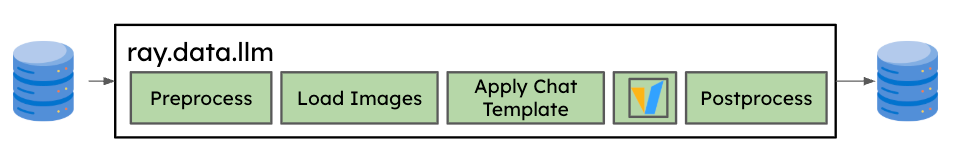
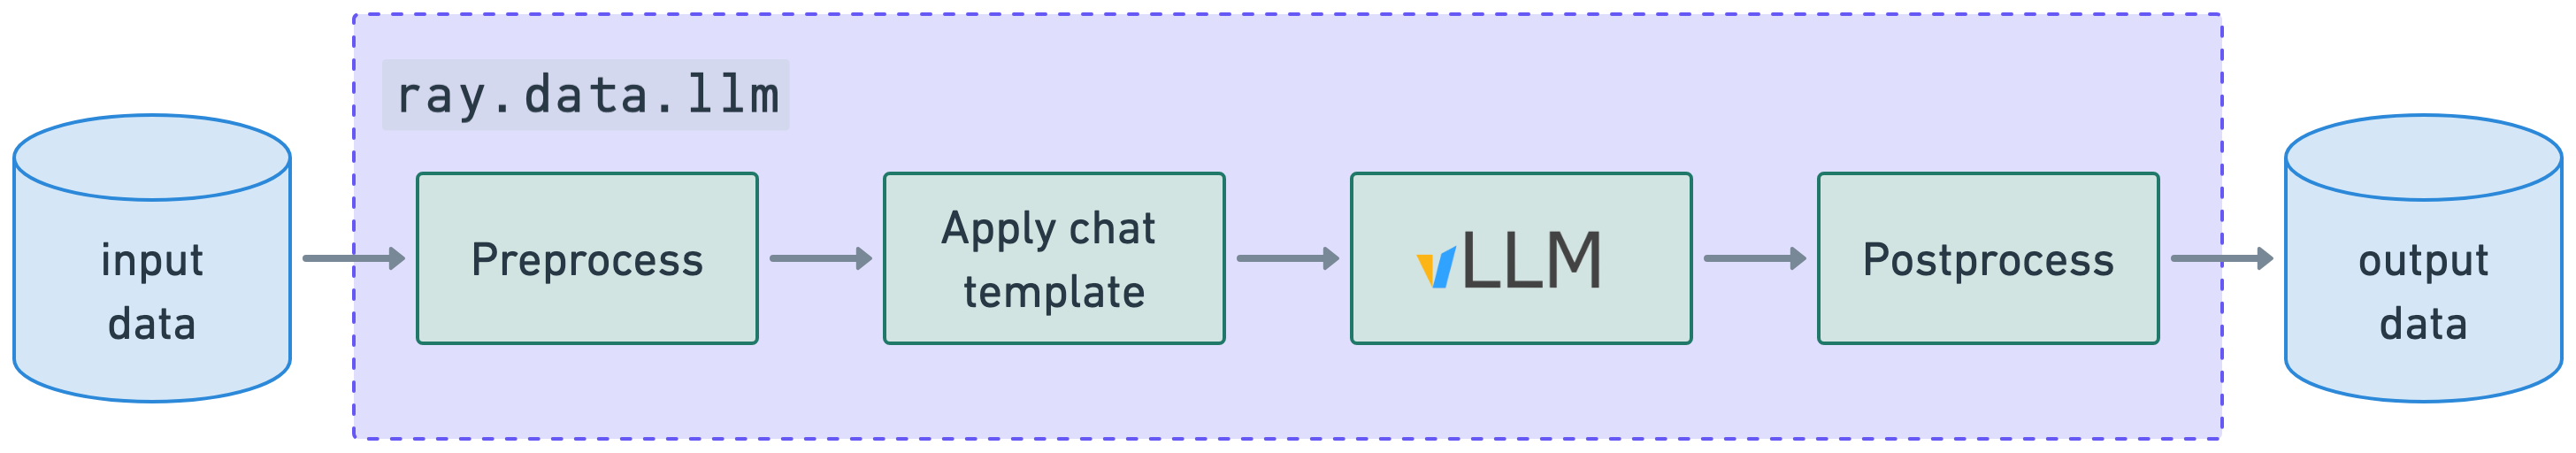
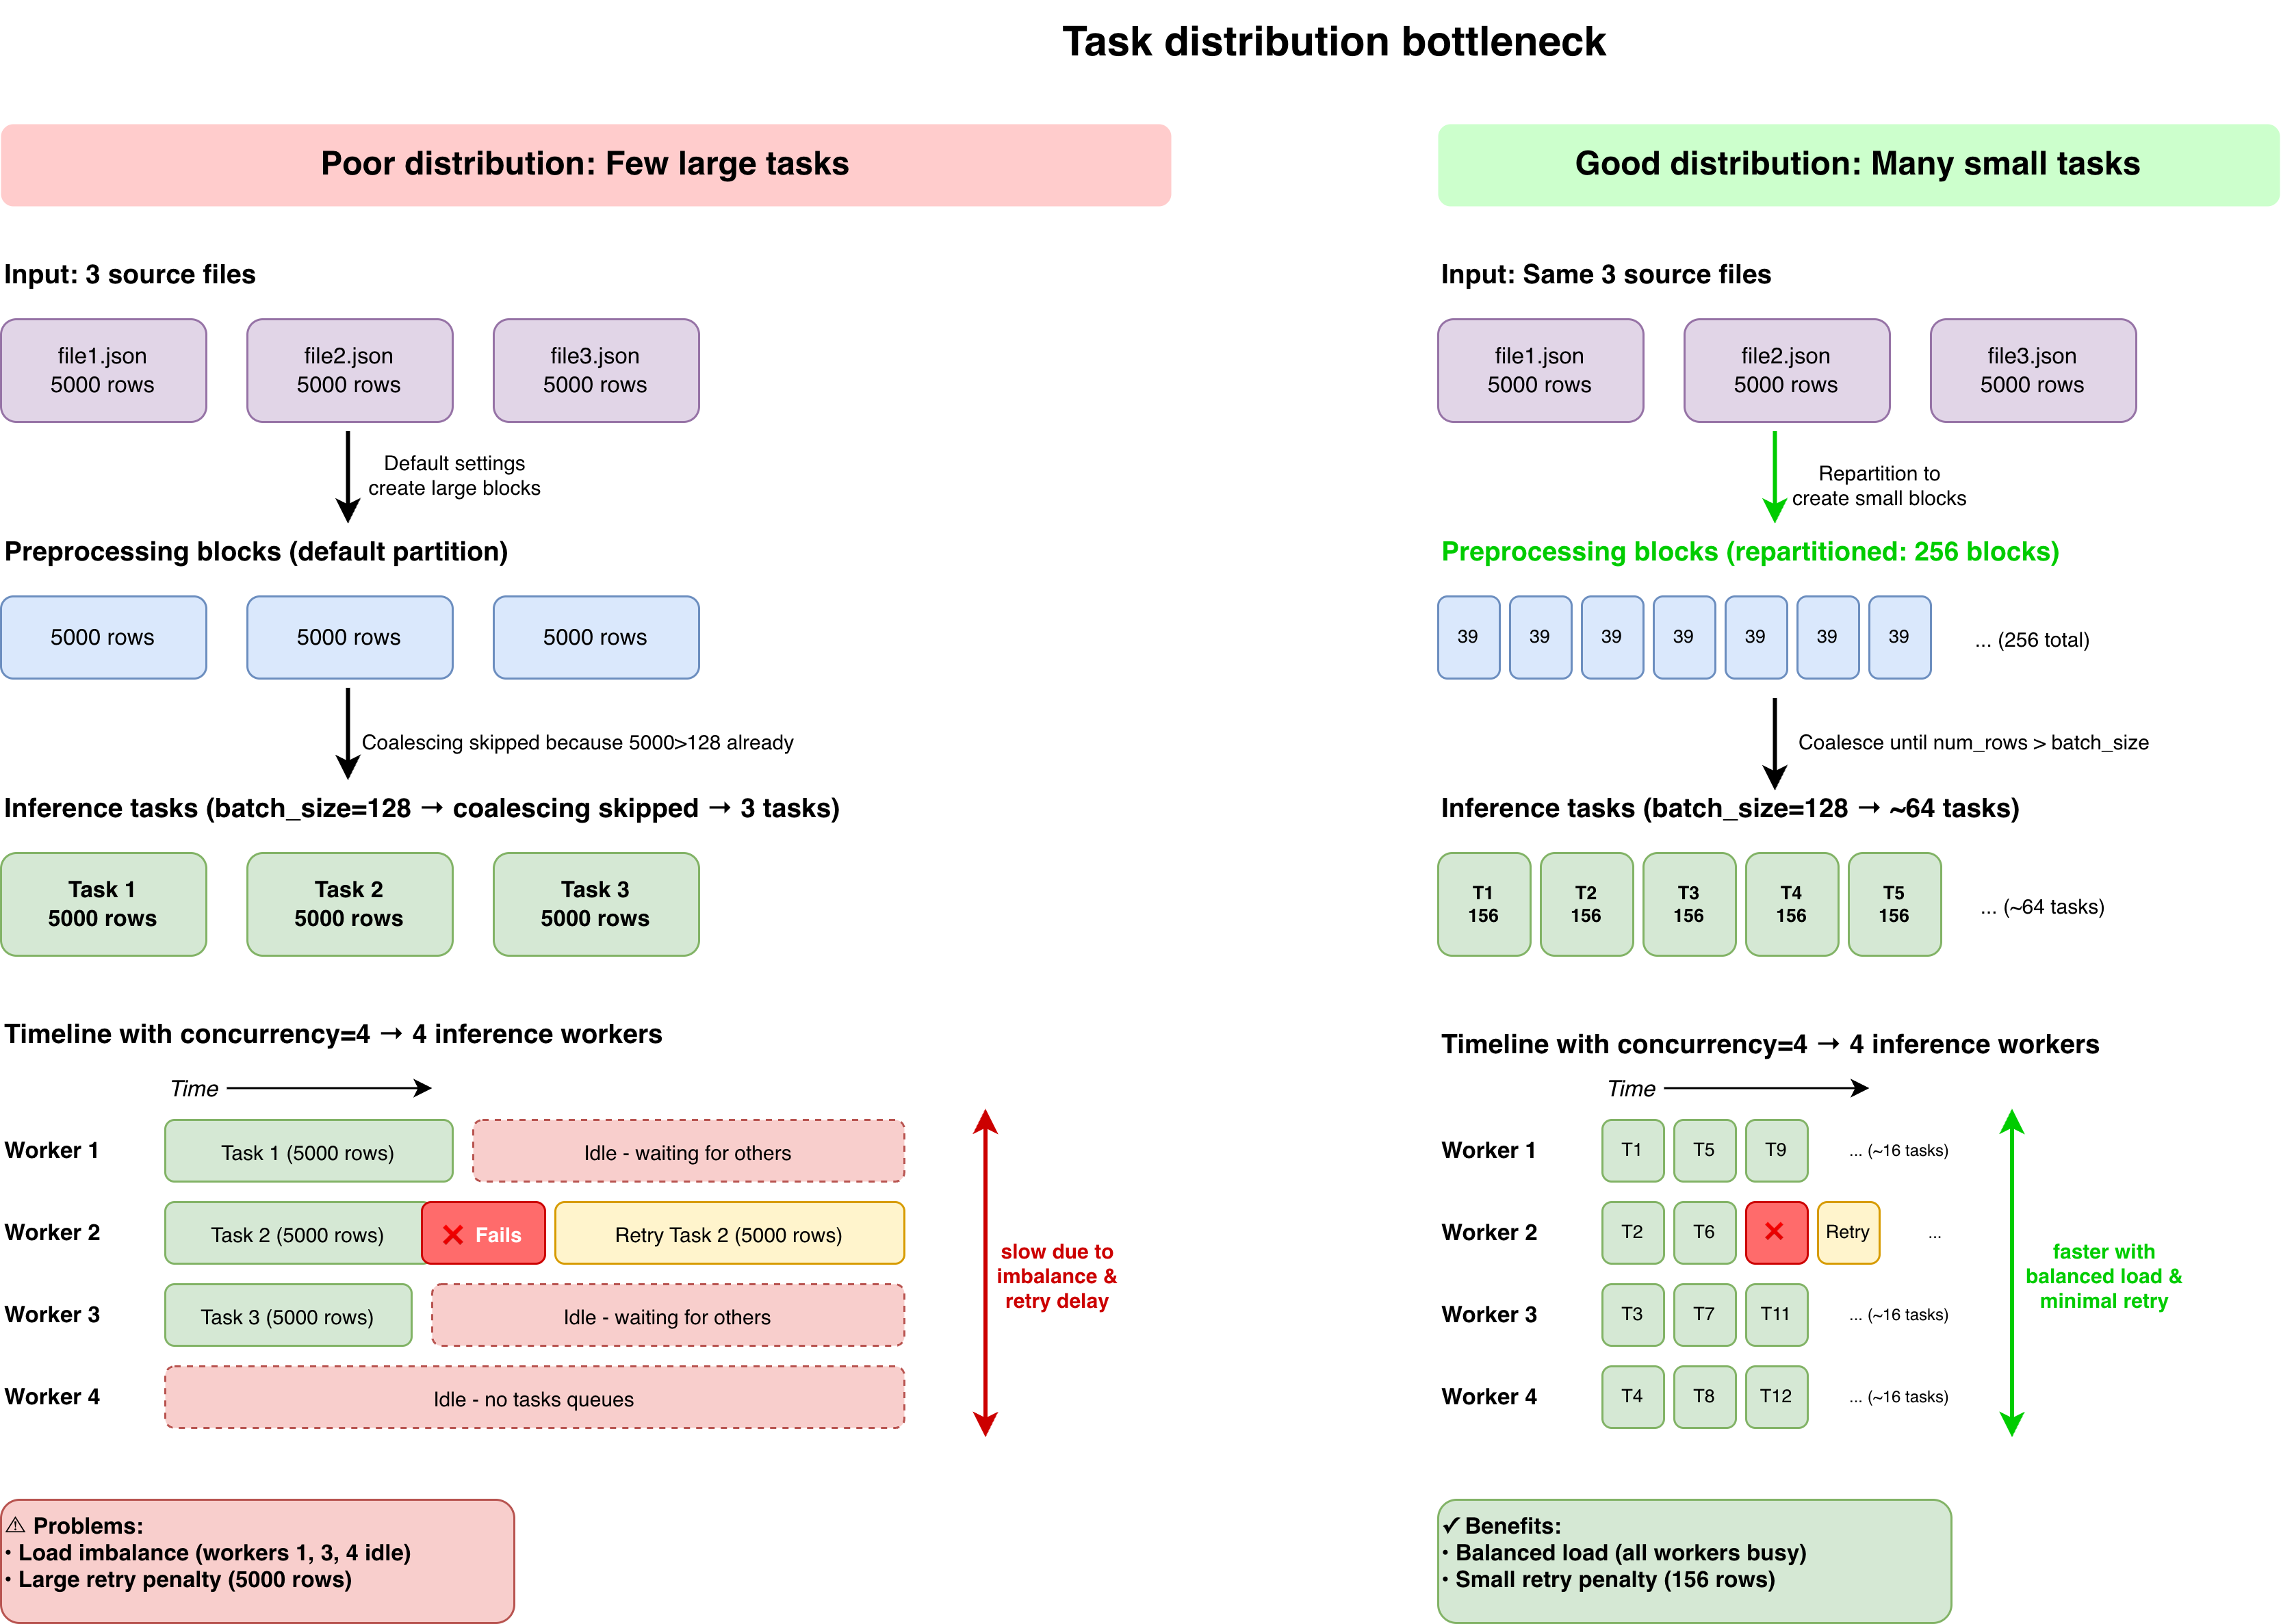
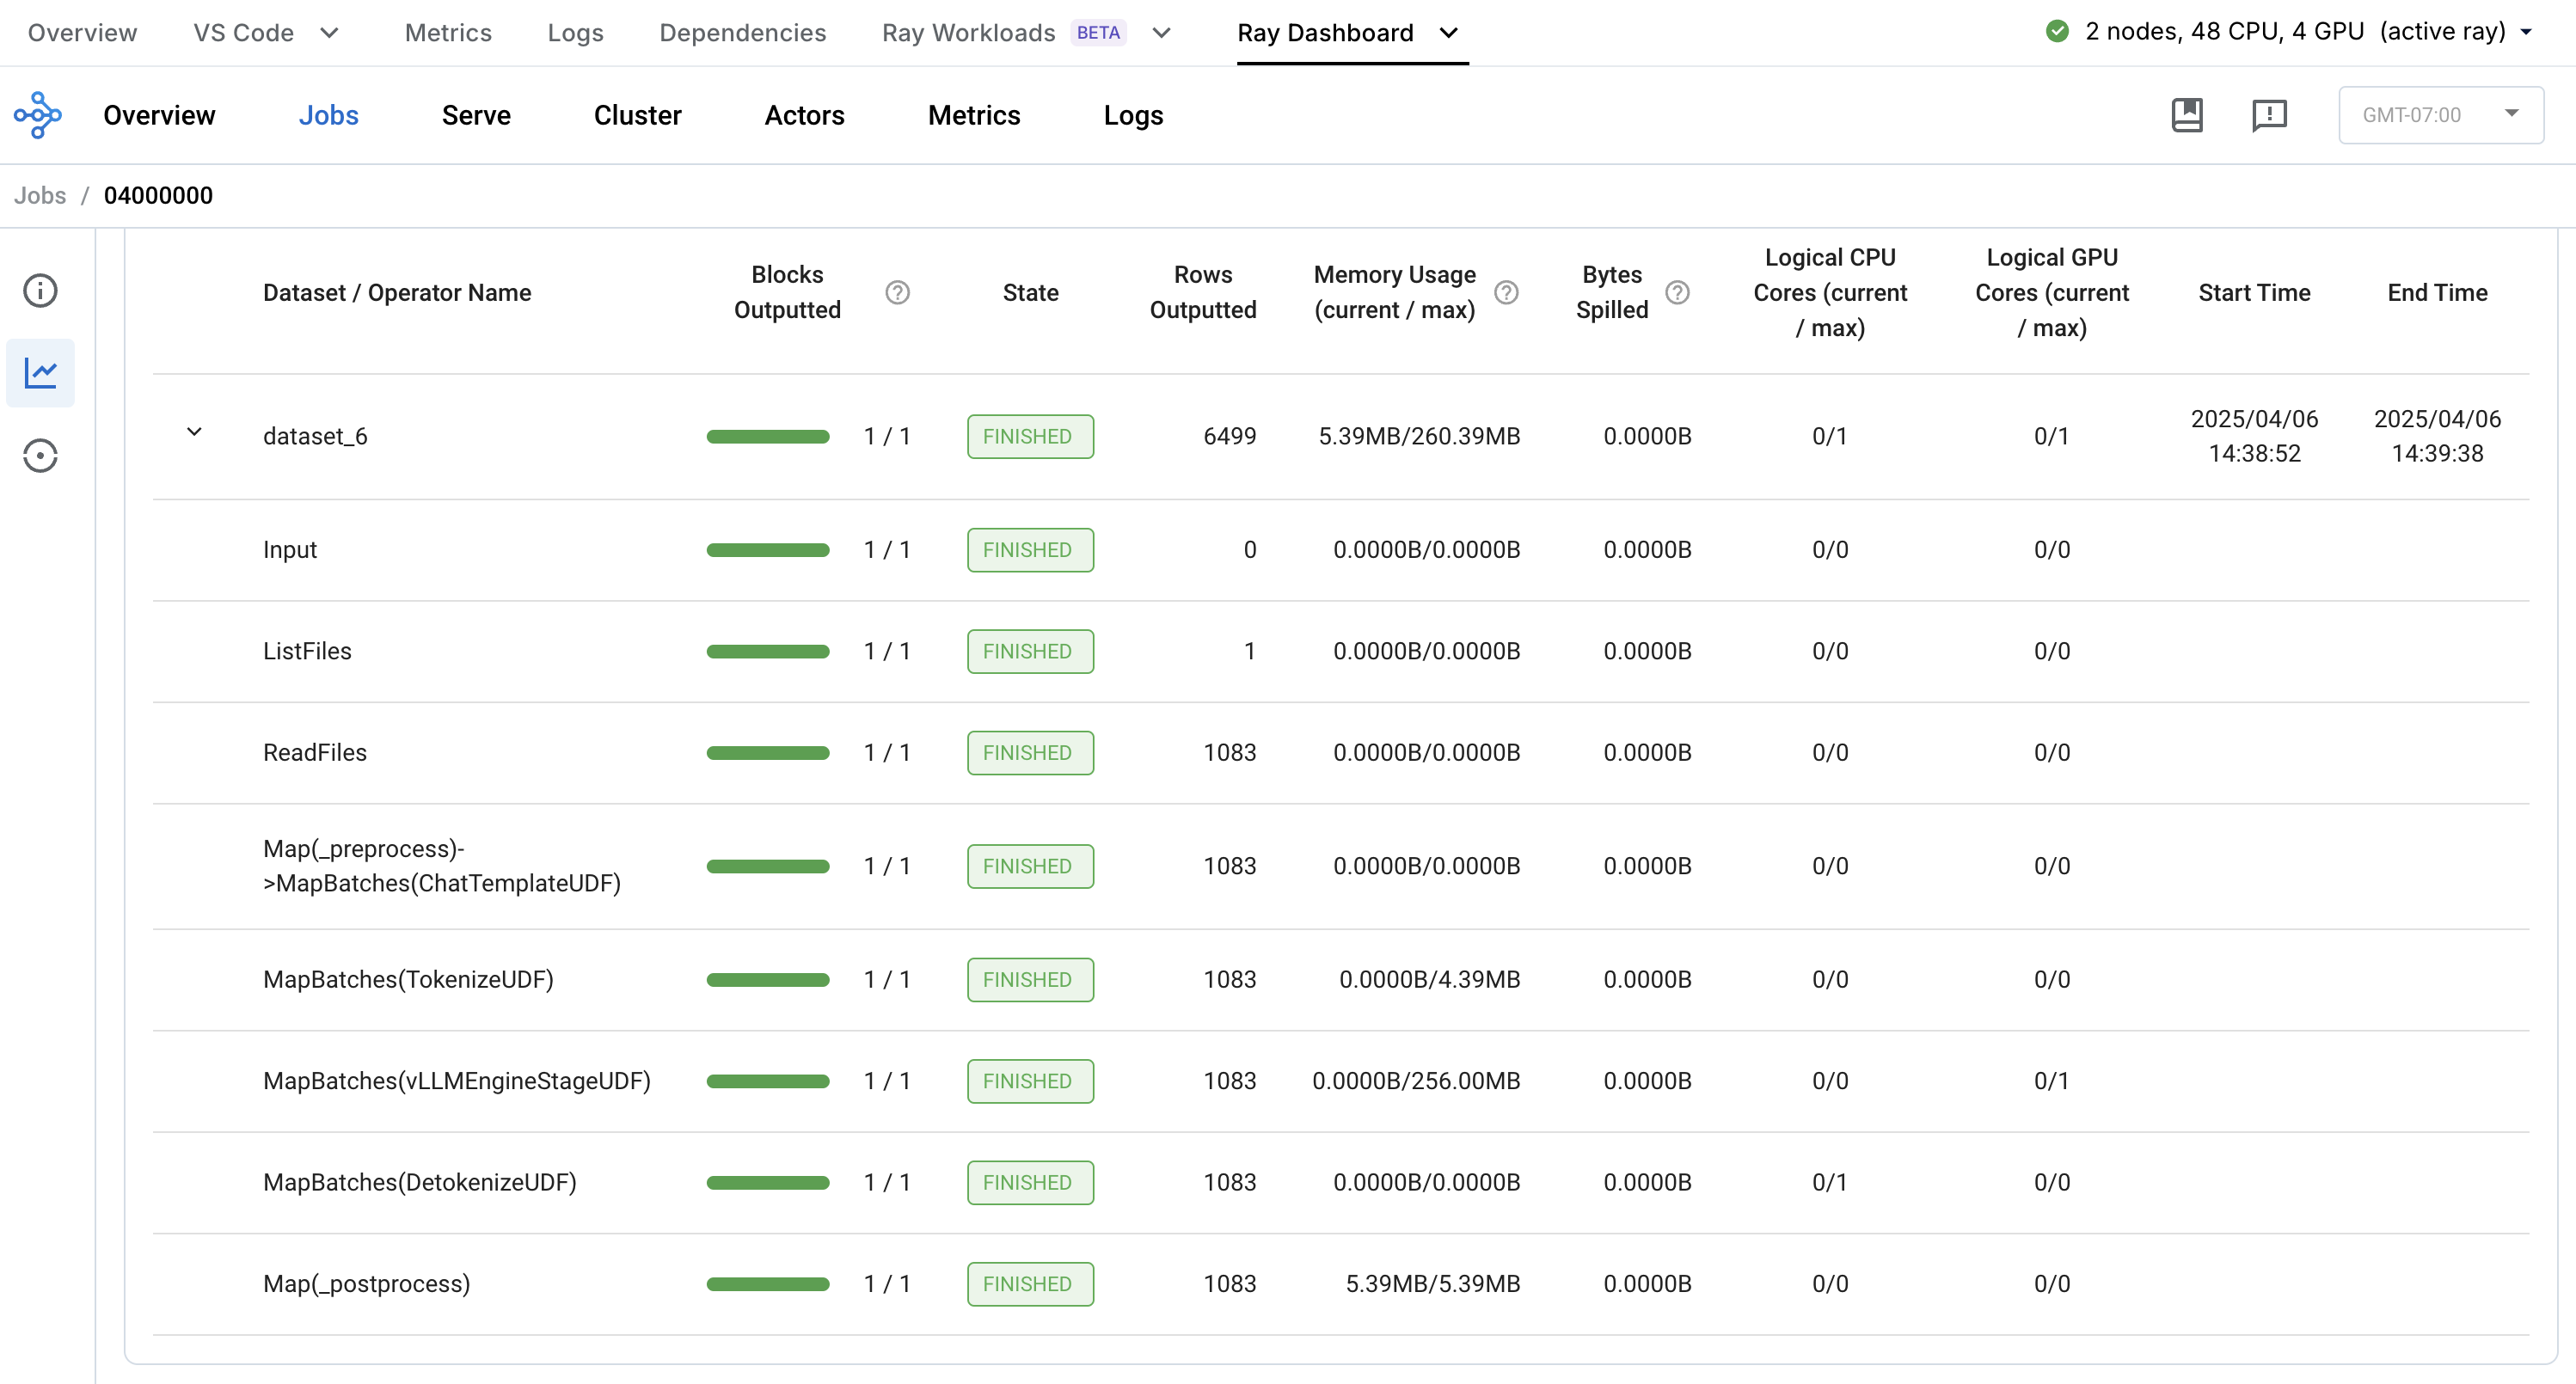
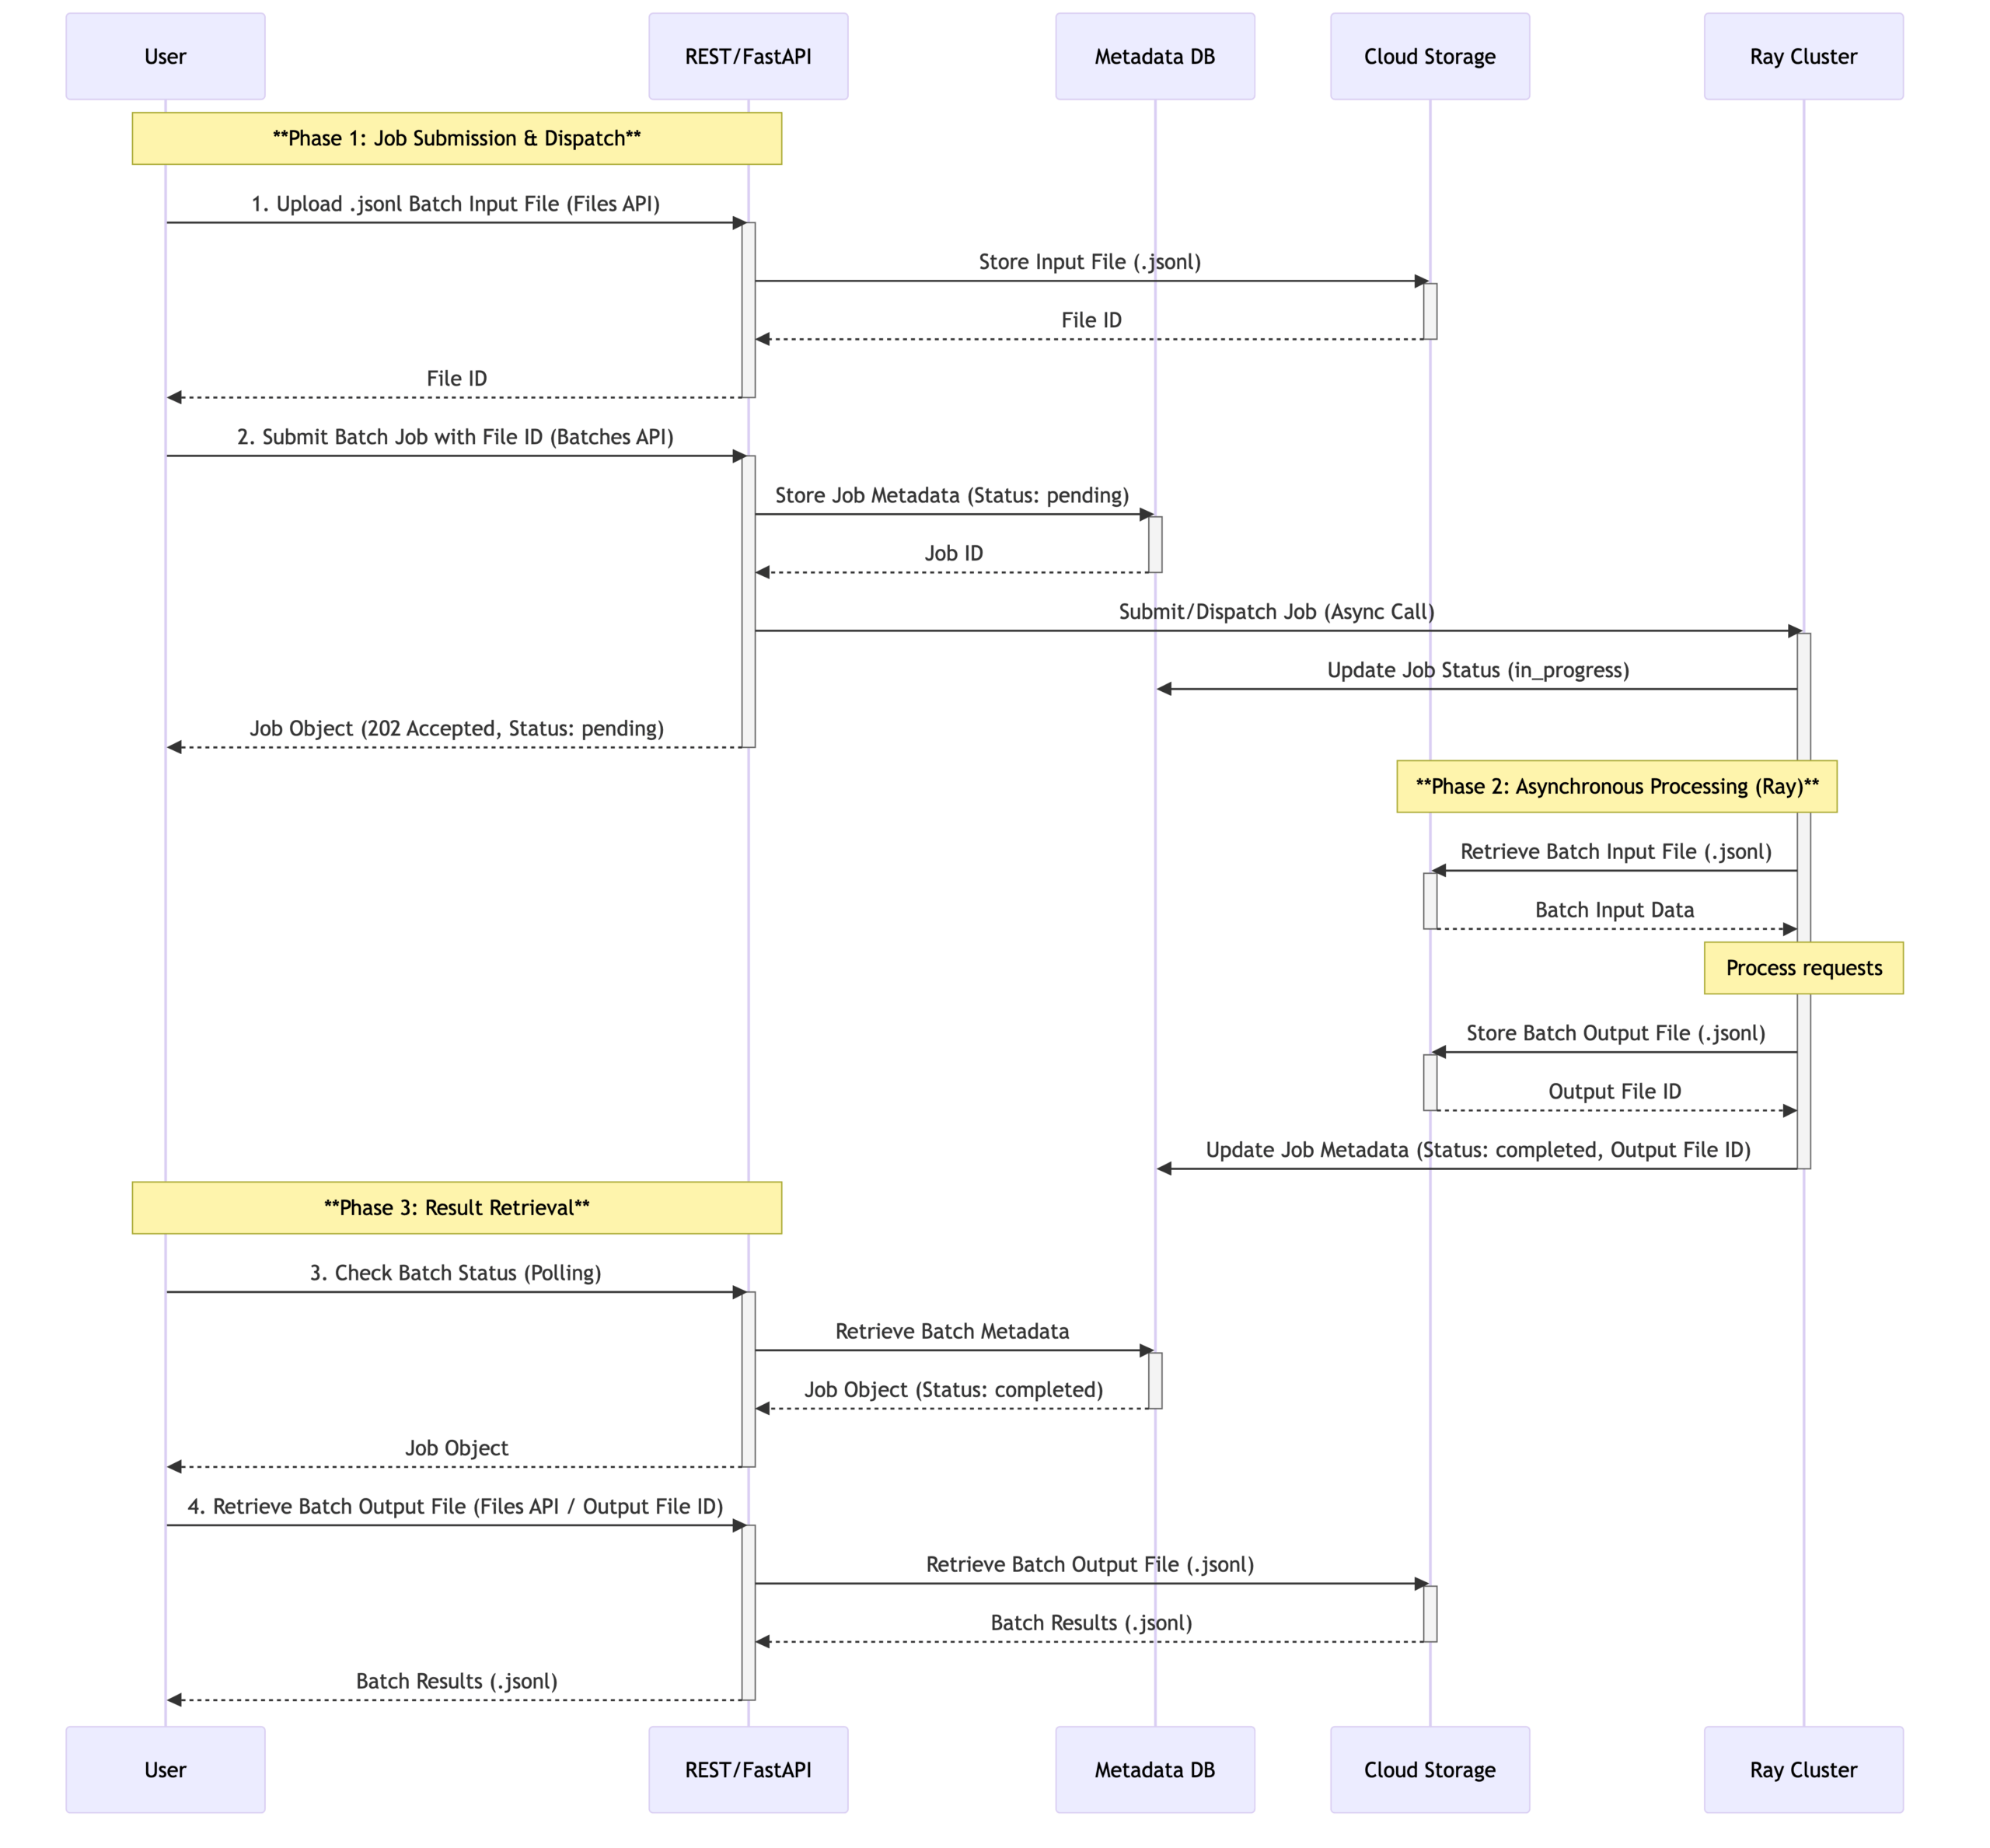
Run batch inference with Ray Data LLM | Anyscale Docs
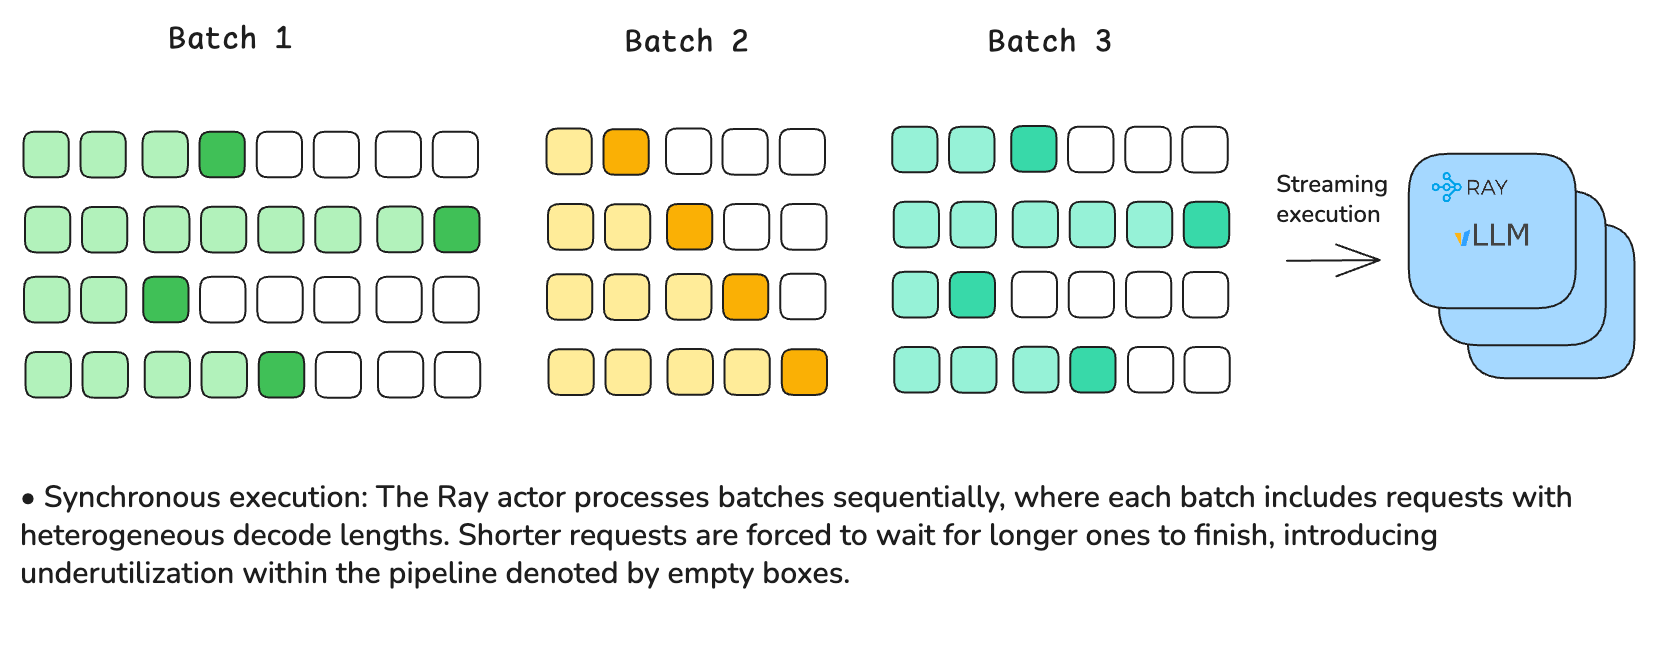
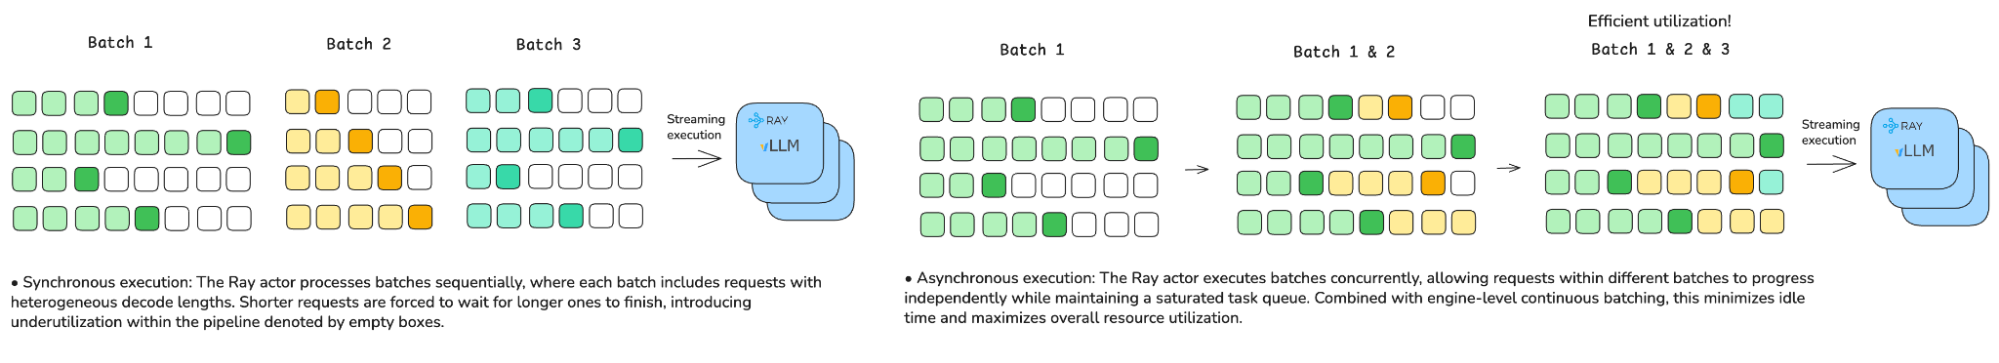
Ray Data LLM enables 2x throughput over vLLM’s synchronous LLM engine ...
Ray Serve LLM on Anyscale: Wide-EP and Disaggregated Serving with vLLM
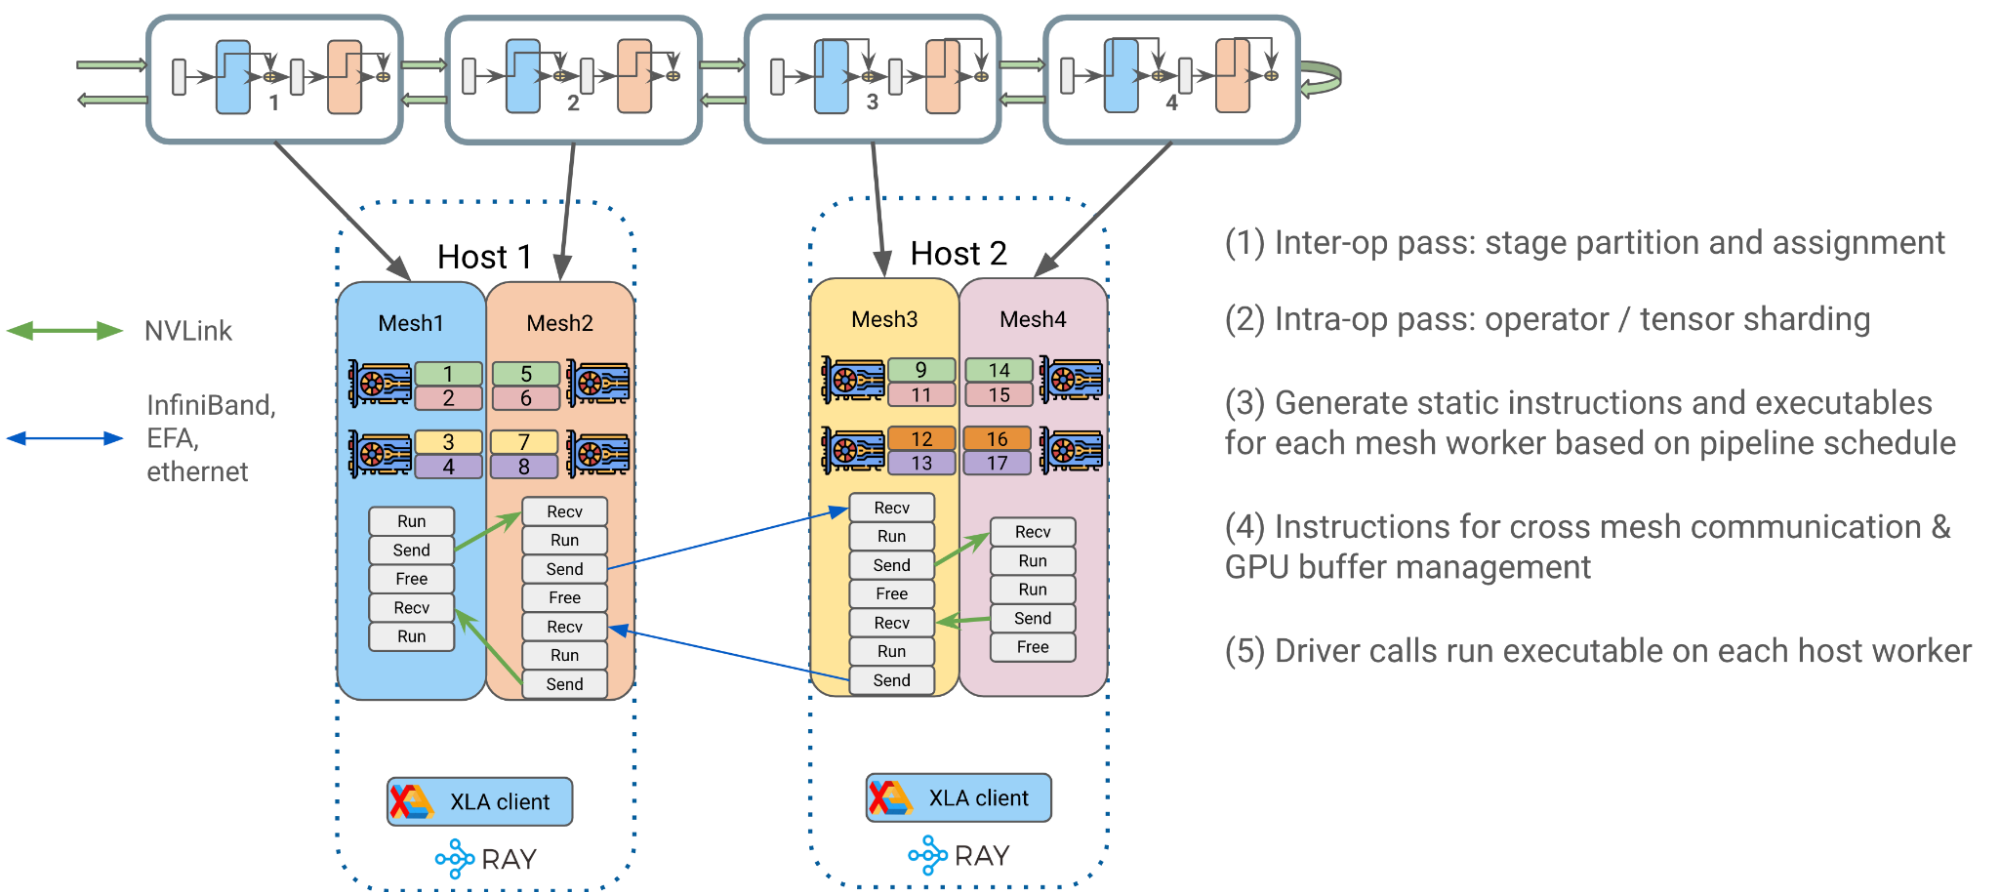
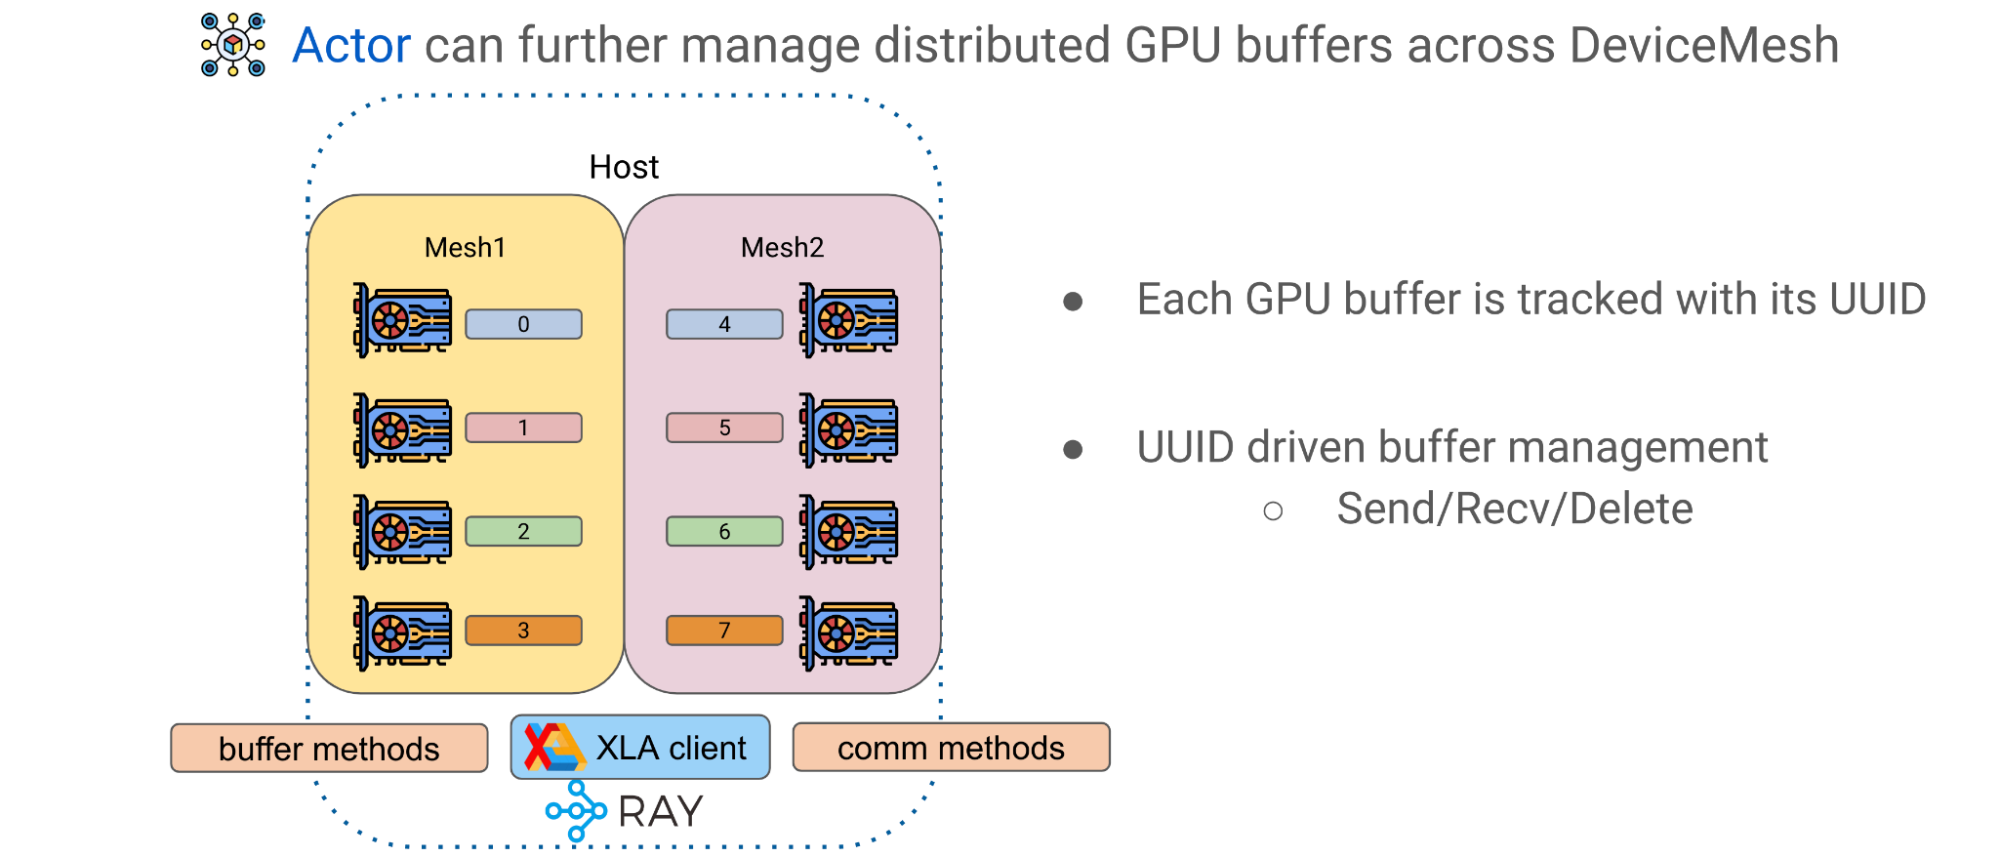
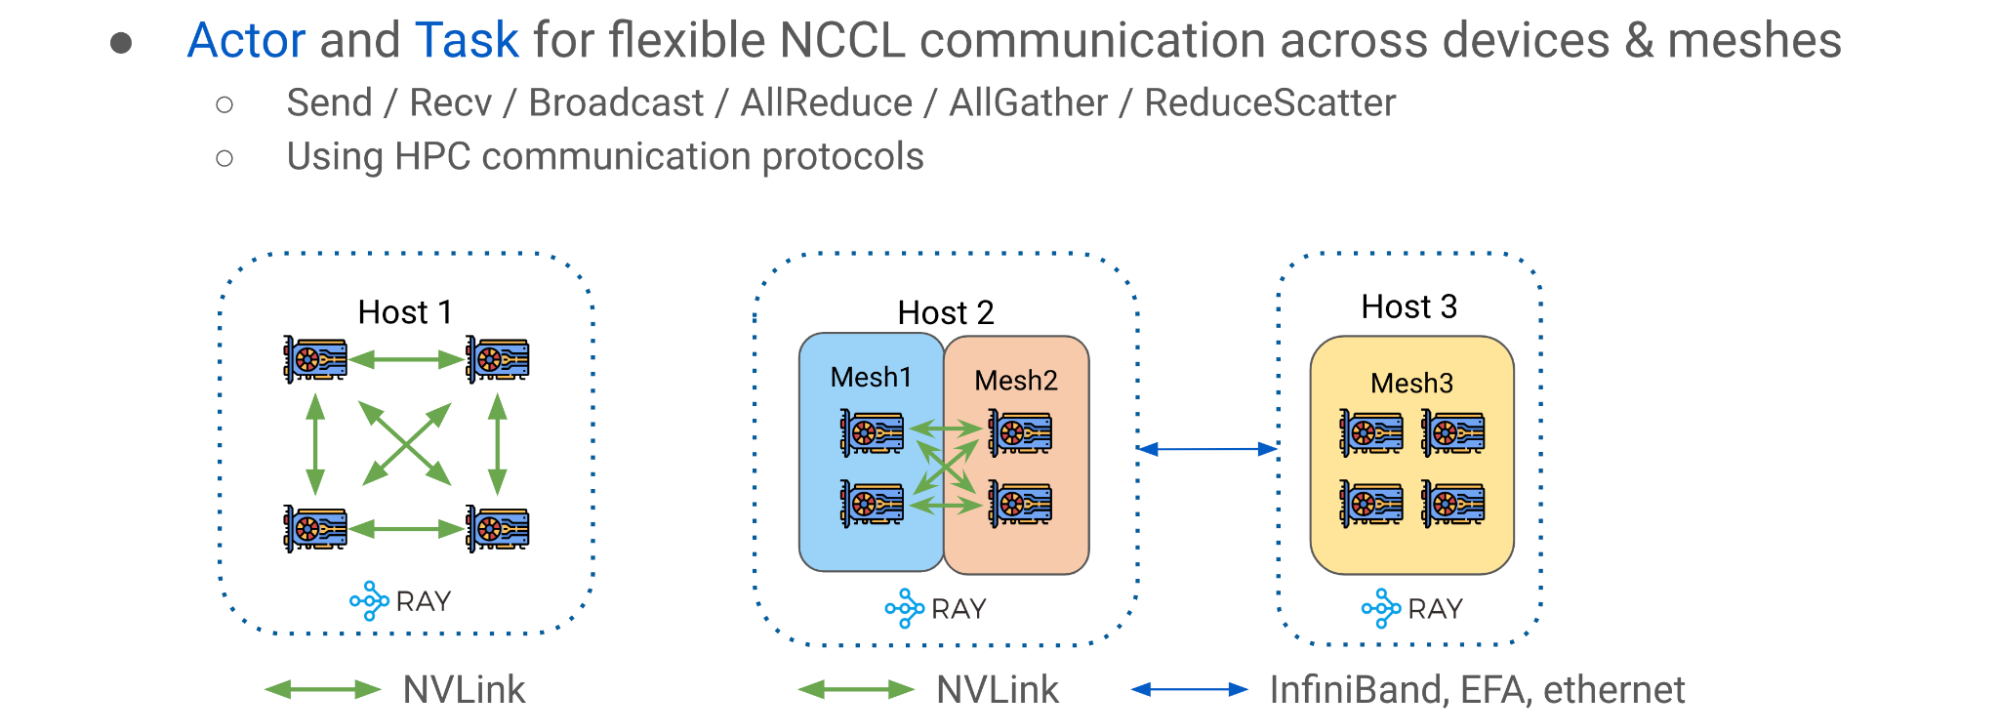
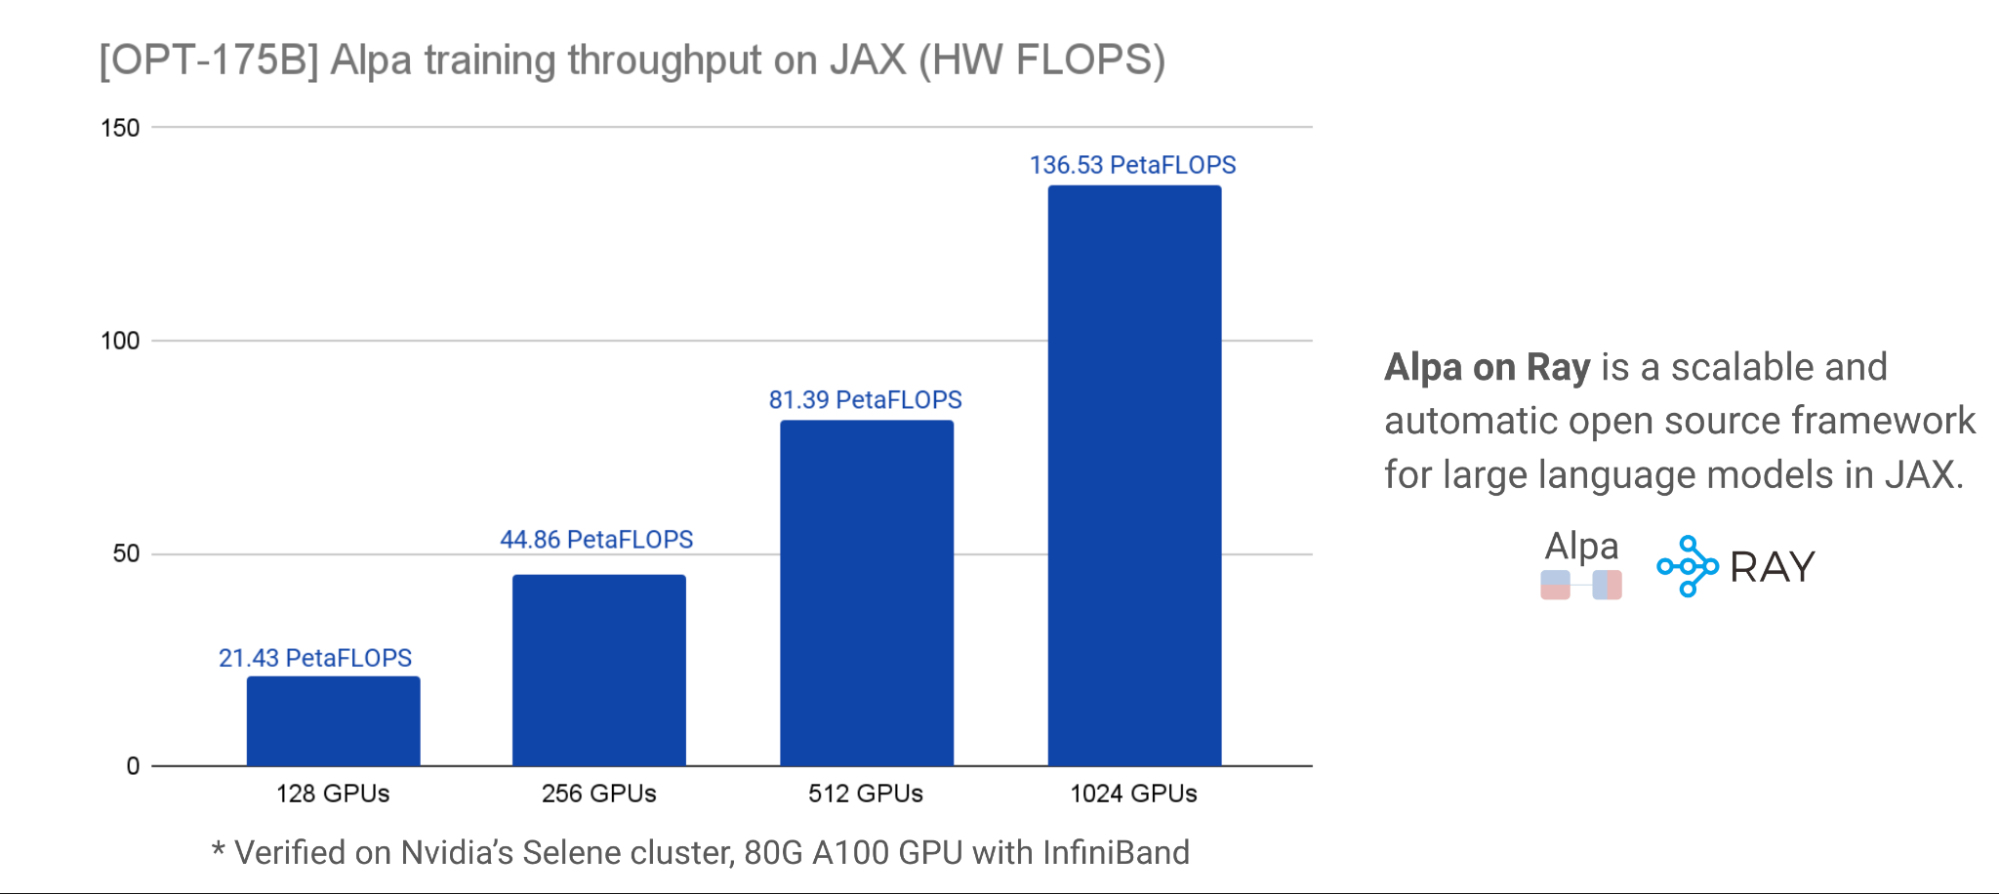
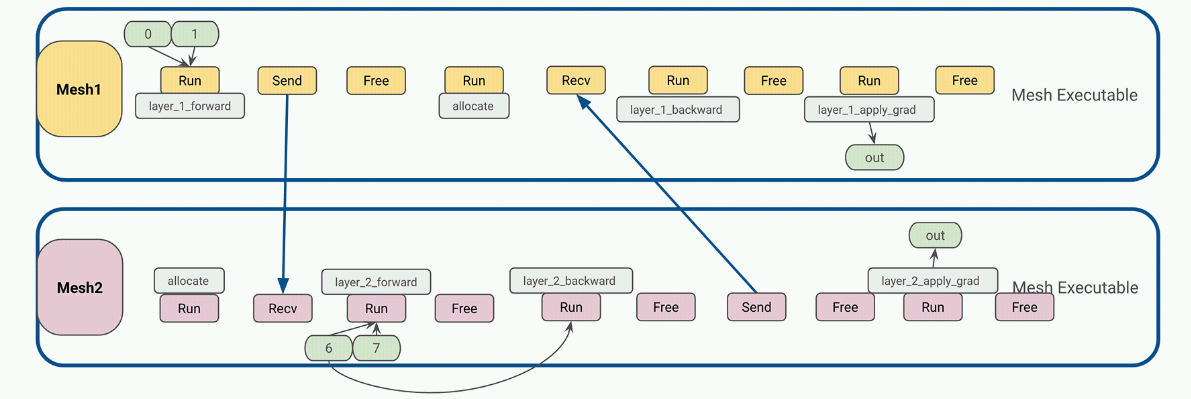
使用 Alpa 和 Ray 在大型 GPU 集群中高效扩展 LLM 训练 - NVIDIA 技术博客
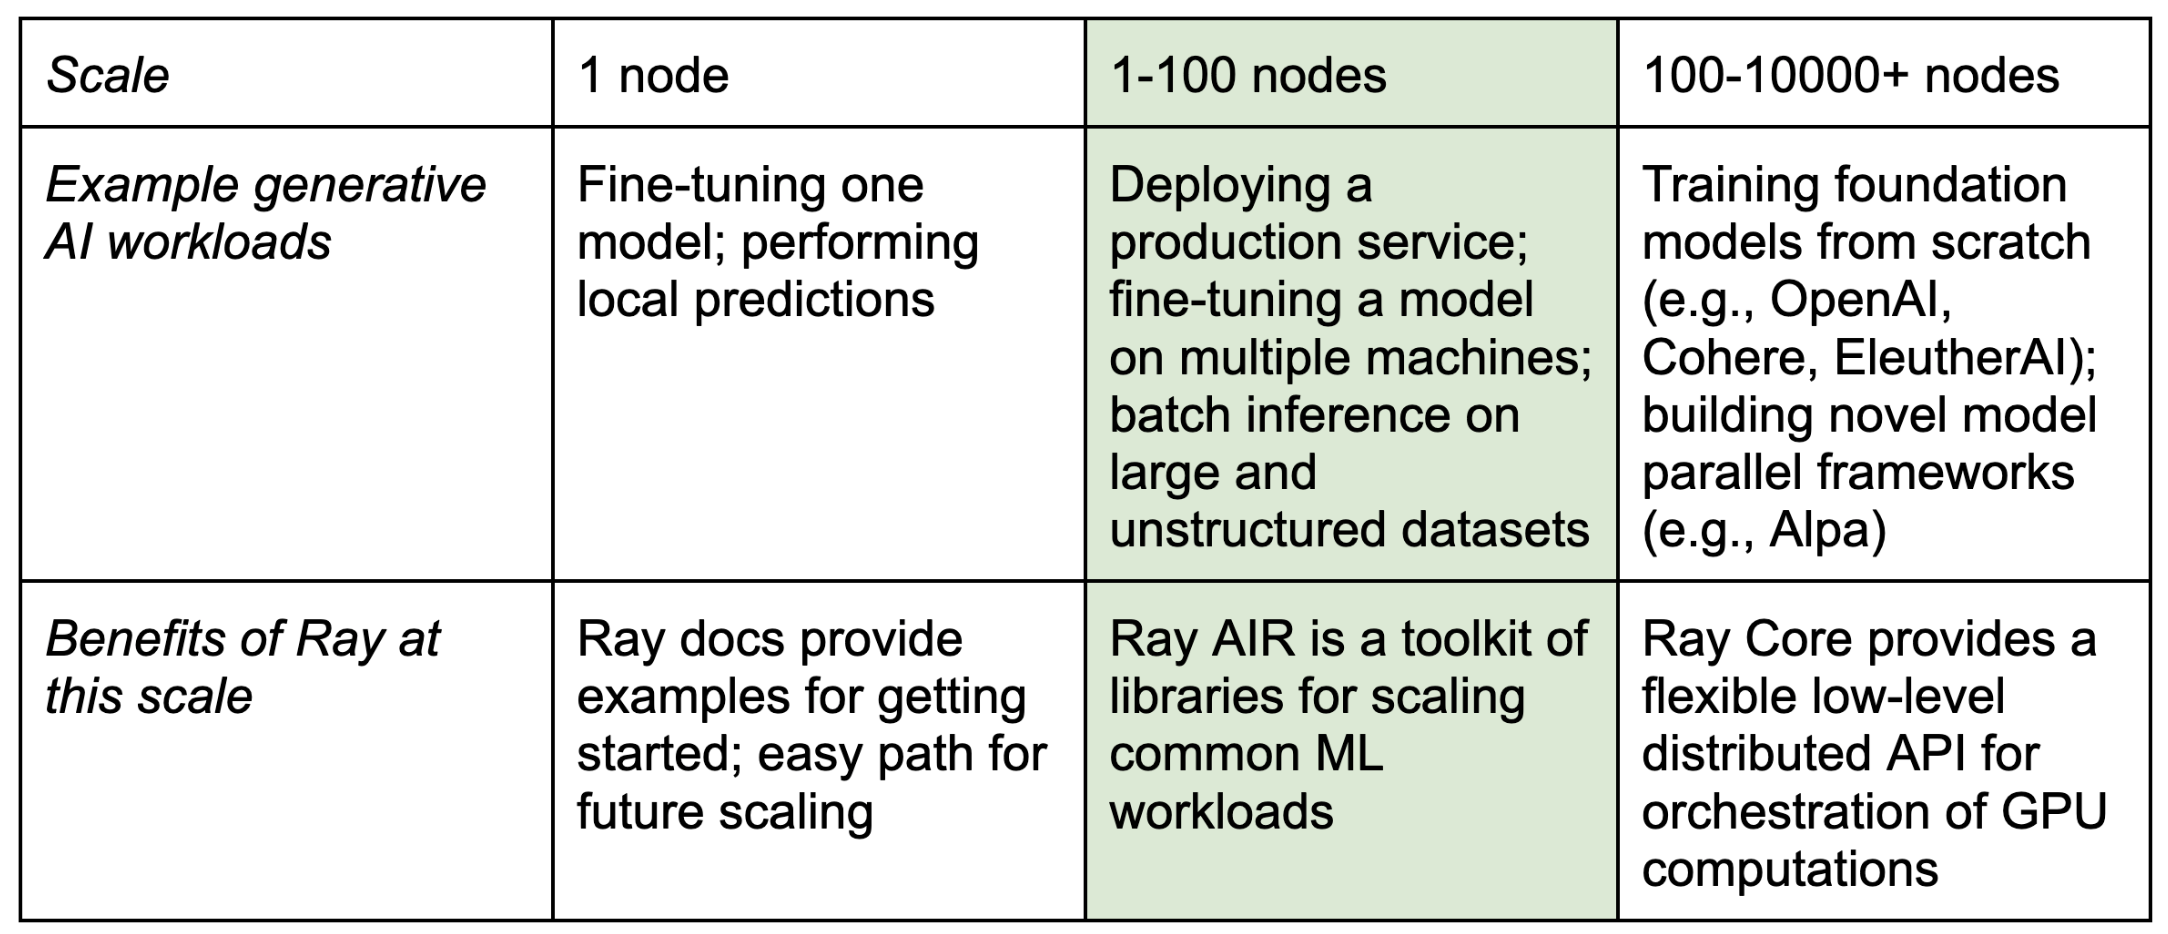
How Ray Solves Generative AI & LLM Infrastructure Challenges
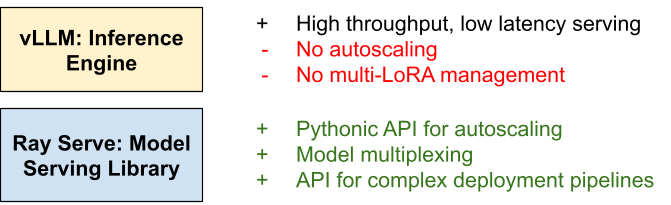
Scaling LLM inference with Ray and vLLM
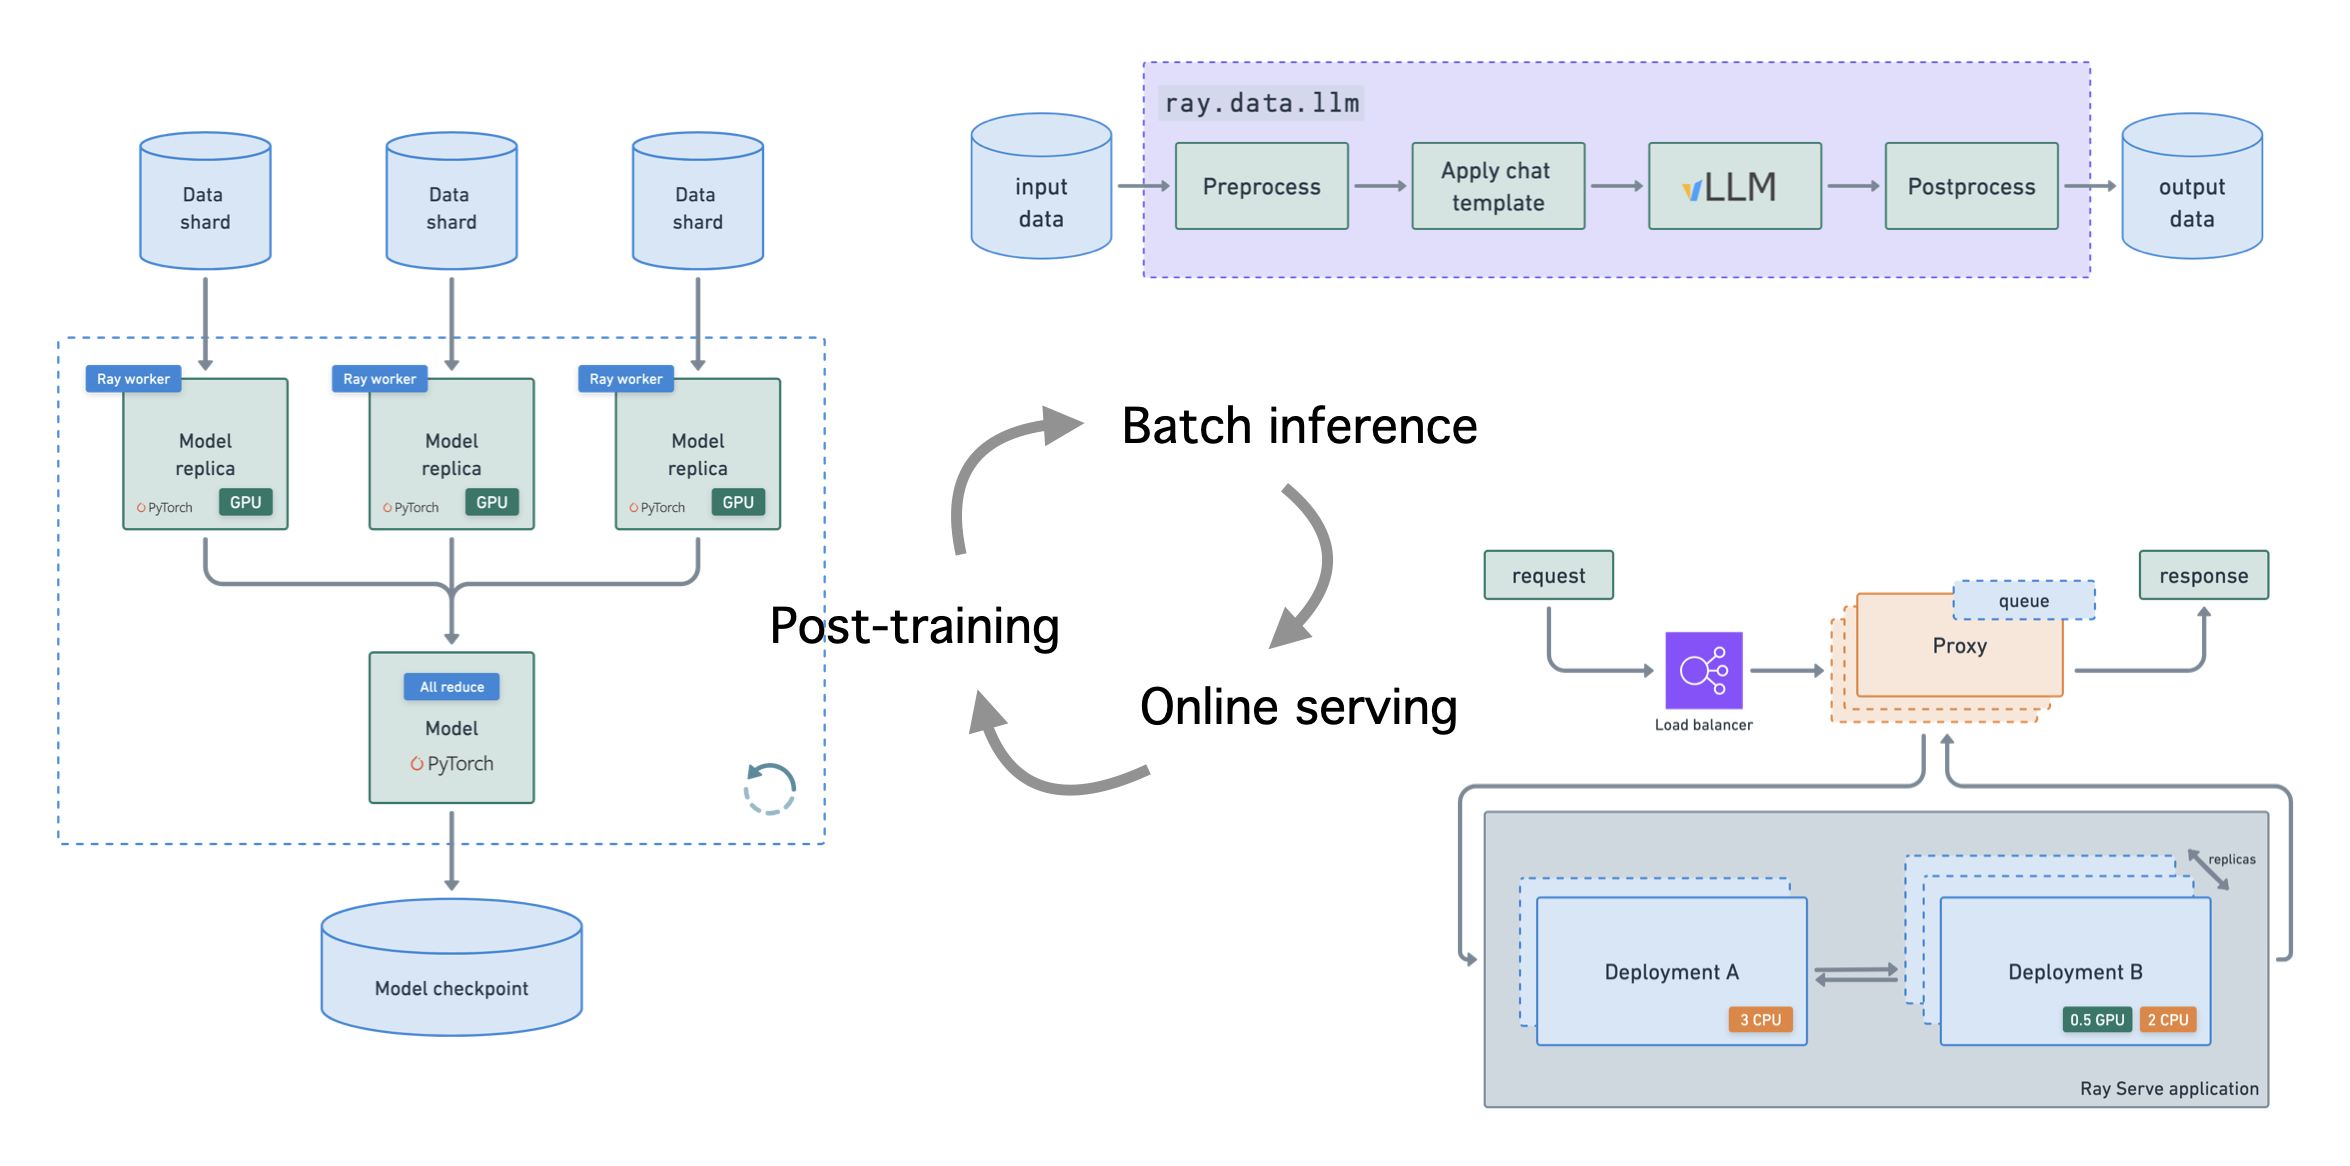
New: Native LLM APIs in Ray Data and Ray Serve
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray
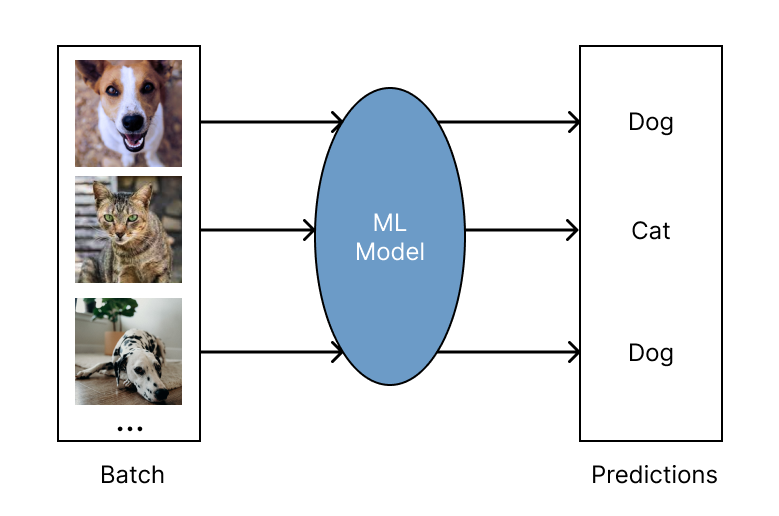
Ray Data LLM vs vLLM: Scalable Batch Inference for Large Language ...
AI/ML Infra Meetup | The power of Ray in the era of LLM and multi ...
LLM 训练和推理 — Ray 2.53.0 - Ray AI 框架
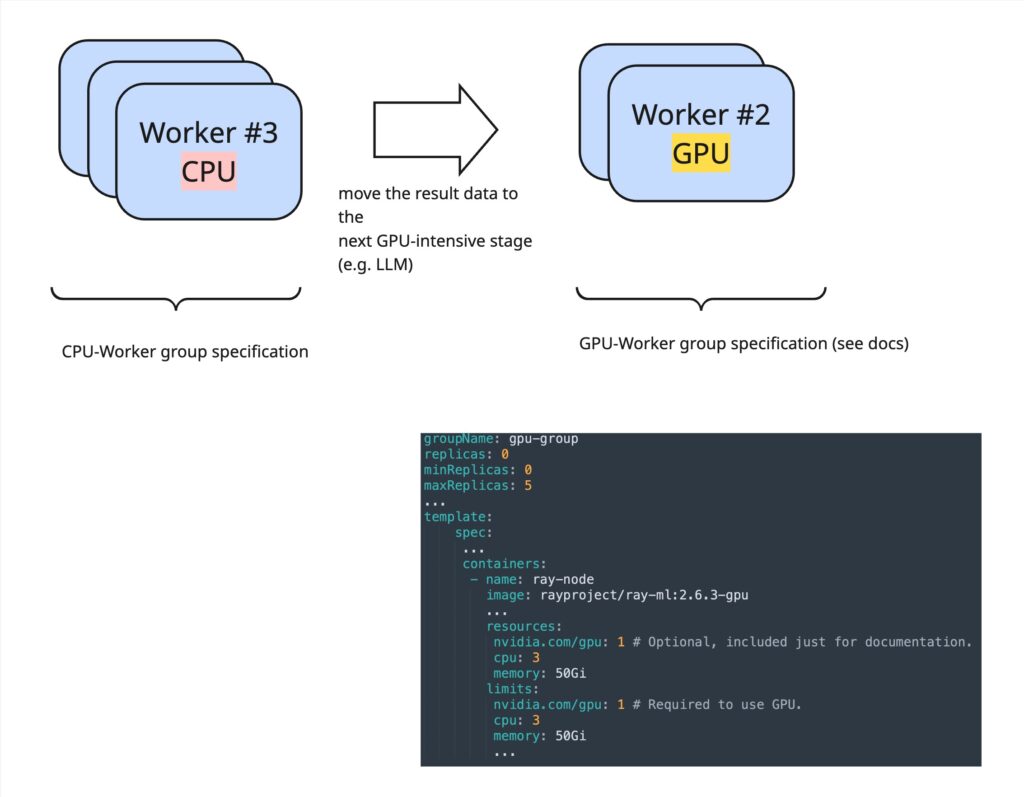
Serve a Large Language Model using Ray Serve LLM on Kubernetes — Ray 2.56.0
Ray Community LLM August Meetup - Speaker Deck
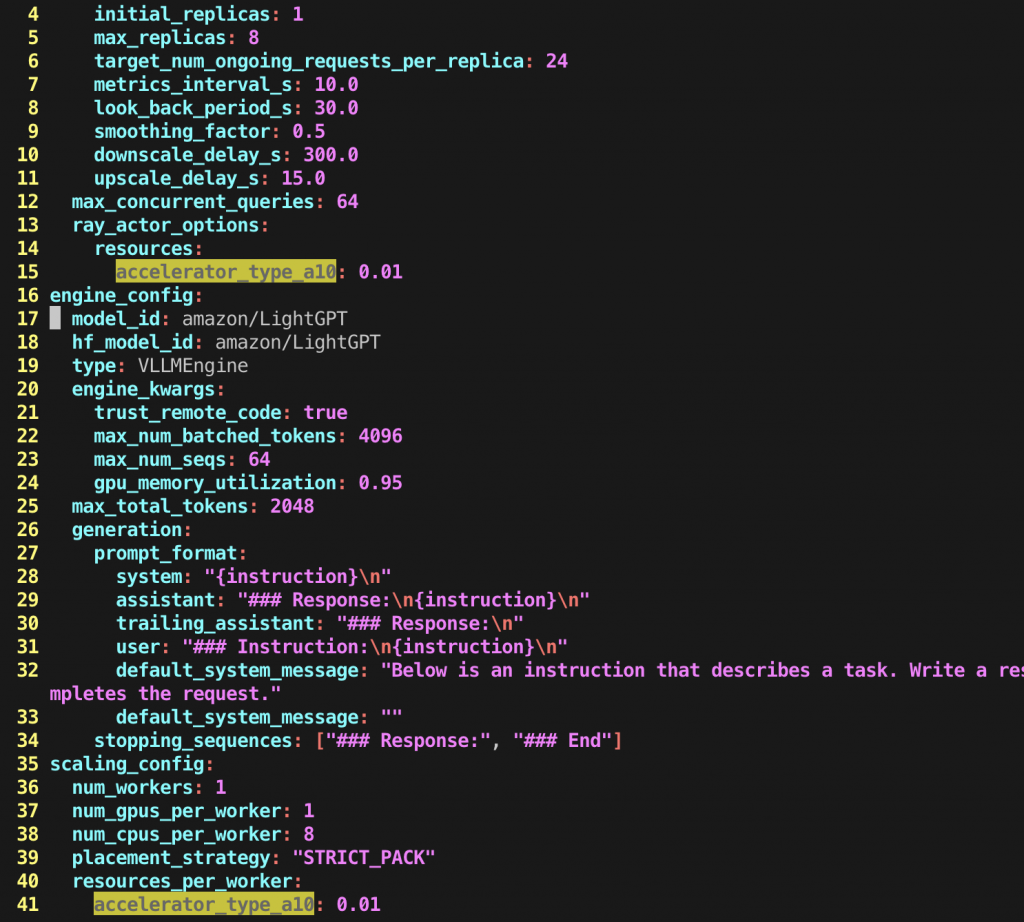
Ray LLM on Nvidia RTX series? · Issue #72 · ray-project/ray-llm · GitHub
vLLM and Ray cluster to start LLM on multiple servers with multiple ...
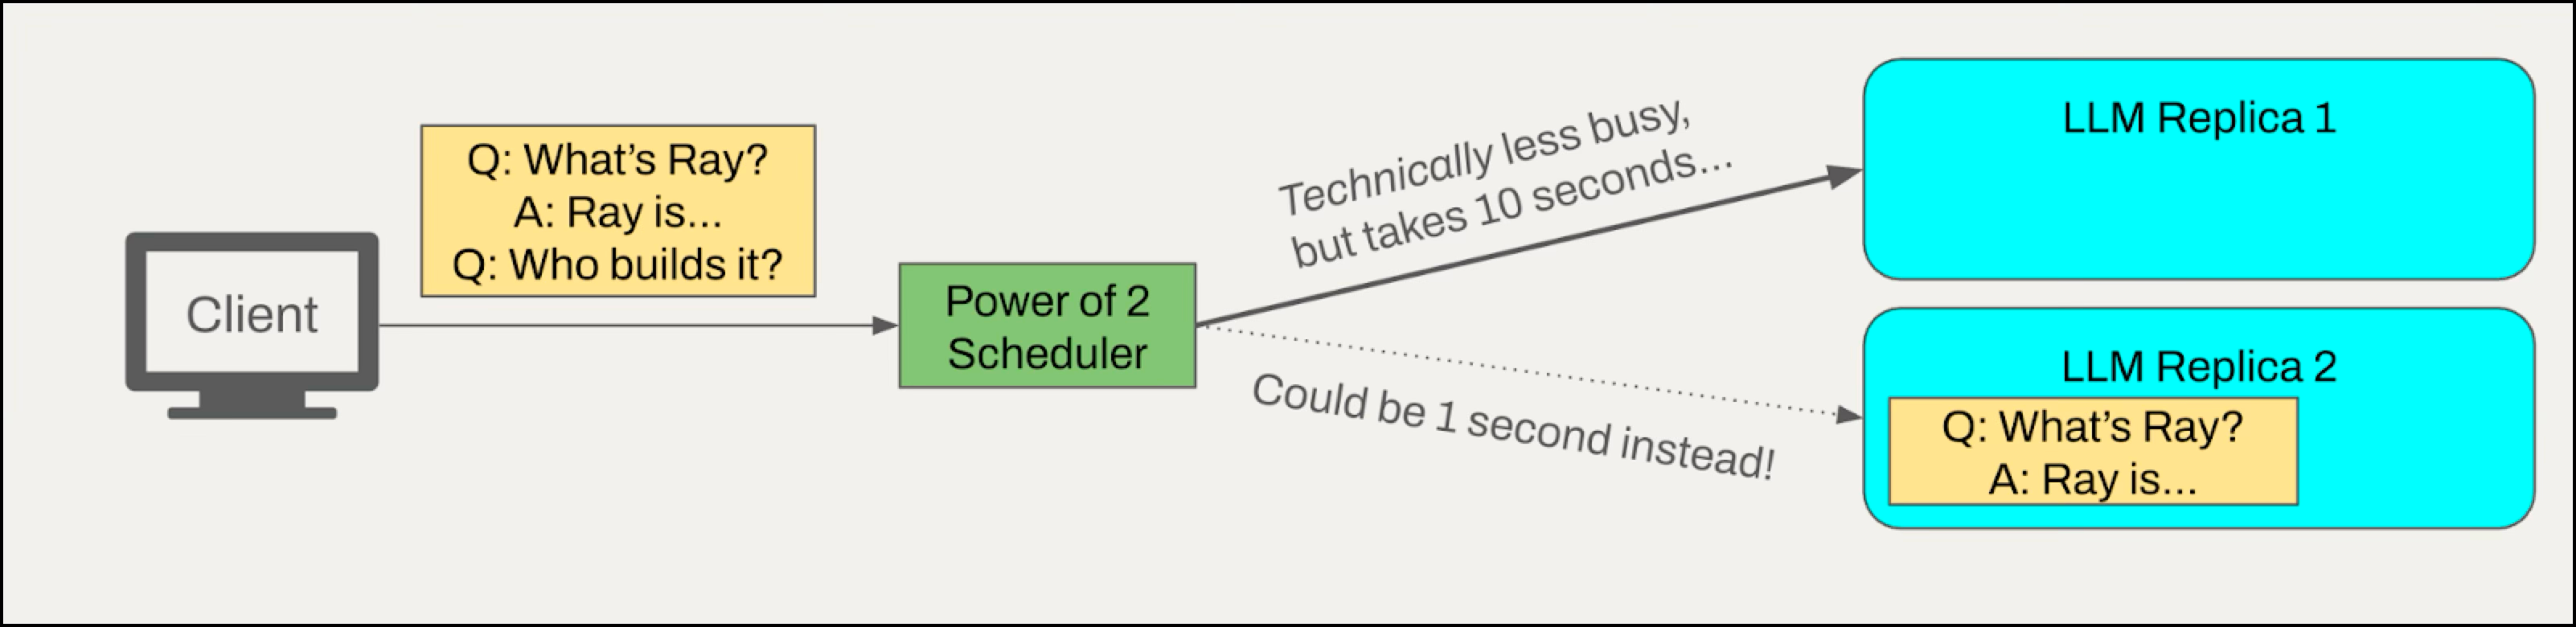
Ray Serve: Reduce LLM Inference Latency by 60% with Custom Request Routing
Ray Data 在 LLM 数据预处理的最佳实践--E-MapReduce-火山引擎
Ray Serve on GPU Cloud: Production LLM Serving Guide (2026) | Spheron Blog
LLM training and inference — Ray 2.54.0
Ray 2.44: Scaling LLM inference with Ray Data LLM and Ray Serve LLM ...
Optimize throughput for Ray Data LLM batch inference | Anyscale Docs
Ray Libraries in Practice: LLM Workflows
Efficiently Scale LLM Training Across a Large GPU Cluster with Alpa and ...
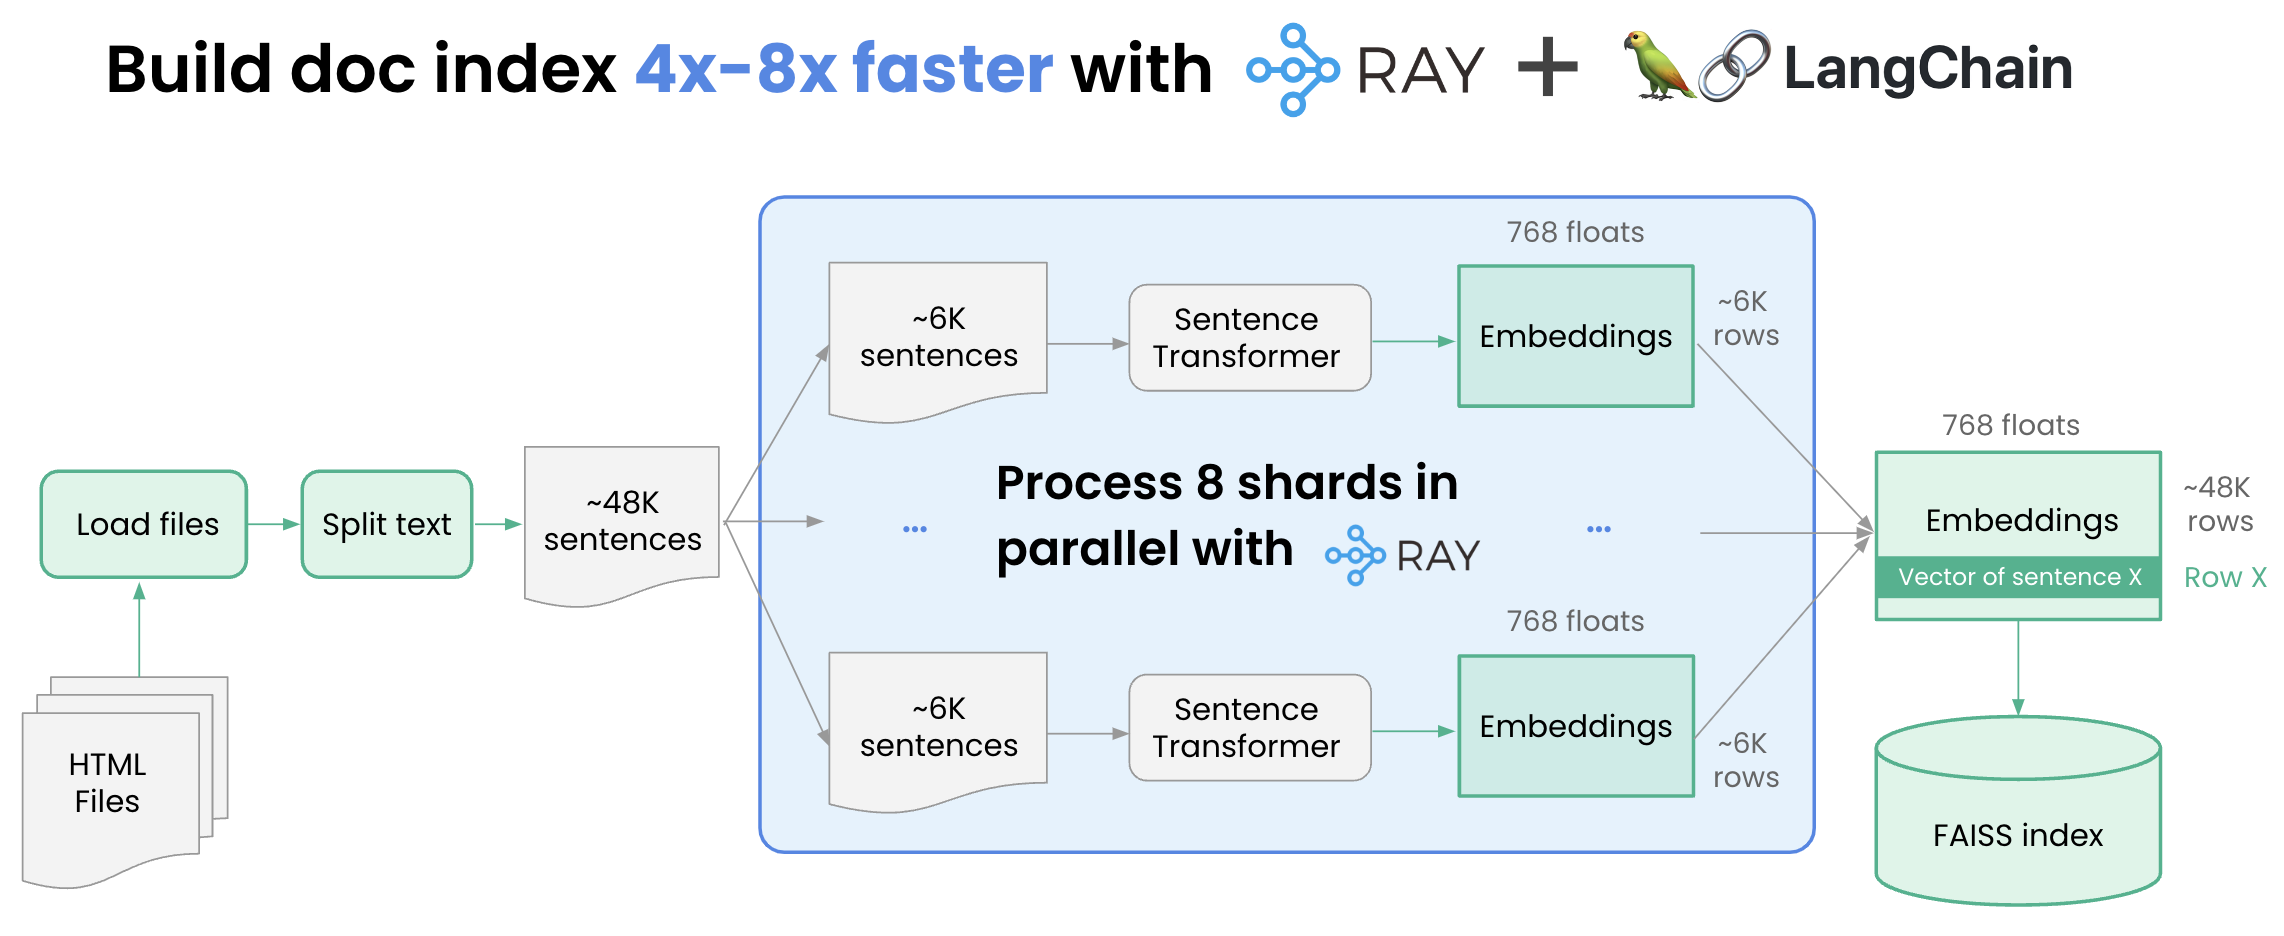
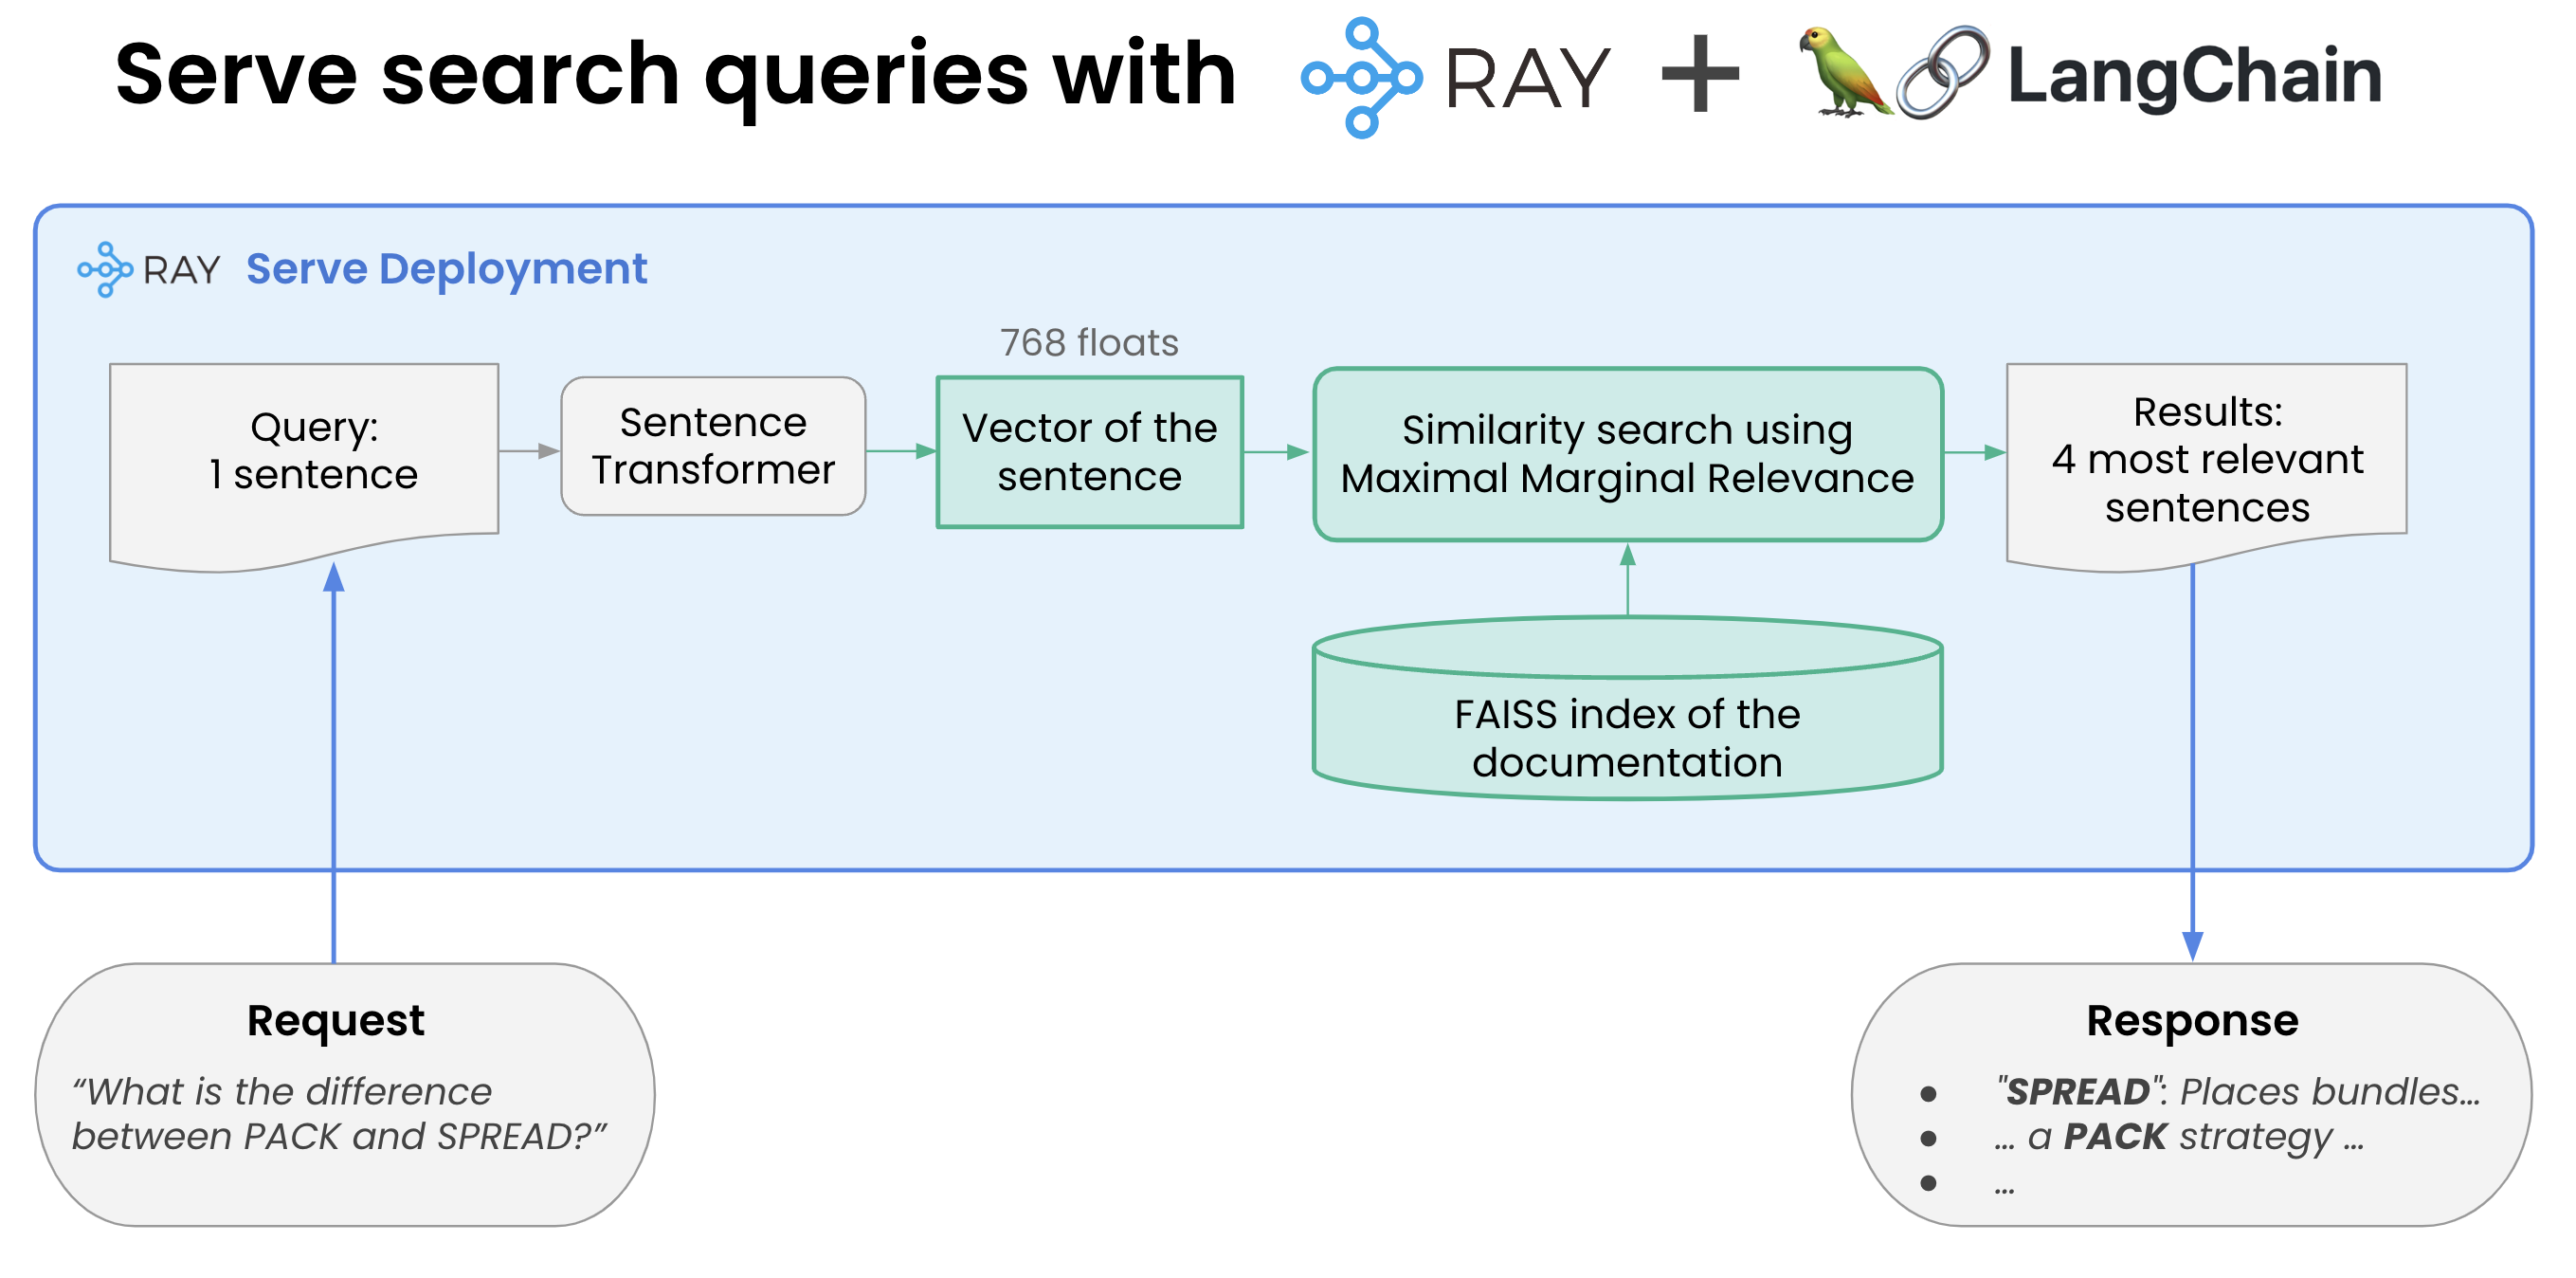
Building an LLM Open-Source Search Engine in 100 Lines
Rheinmetall Vario-Ray LLM - Tiradores de Precisión GC
Architecture overview — Ray 2.59.0
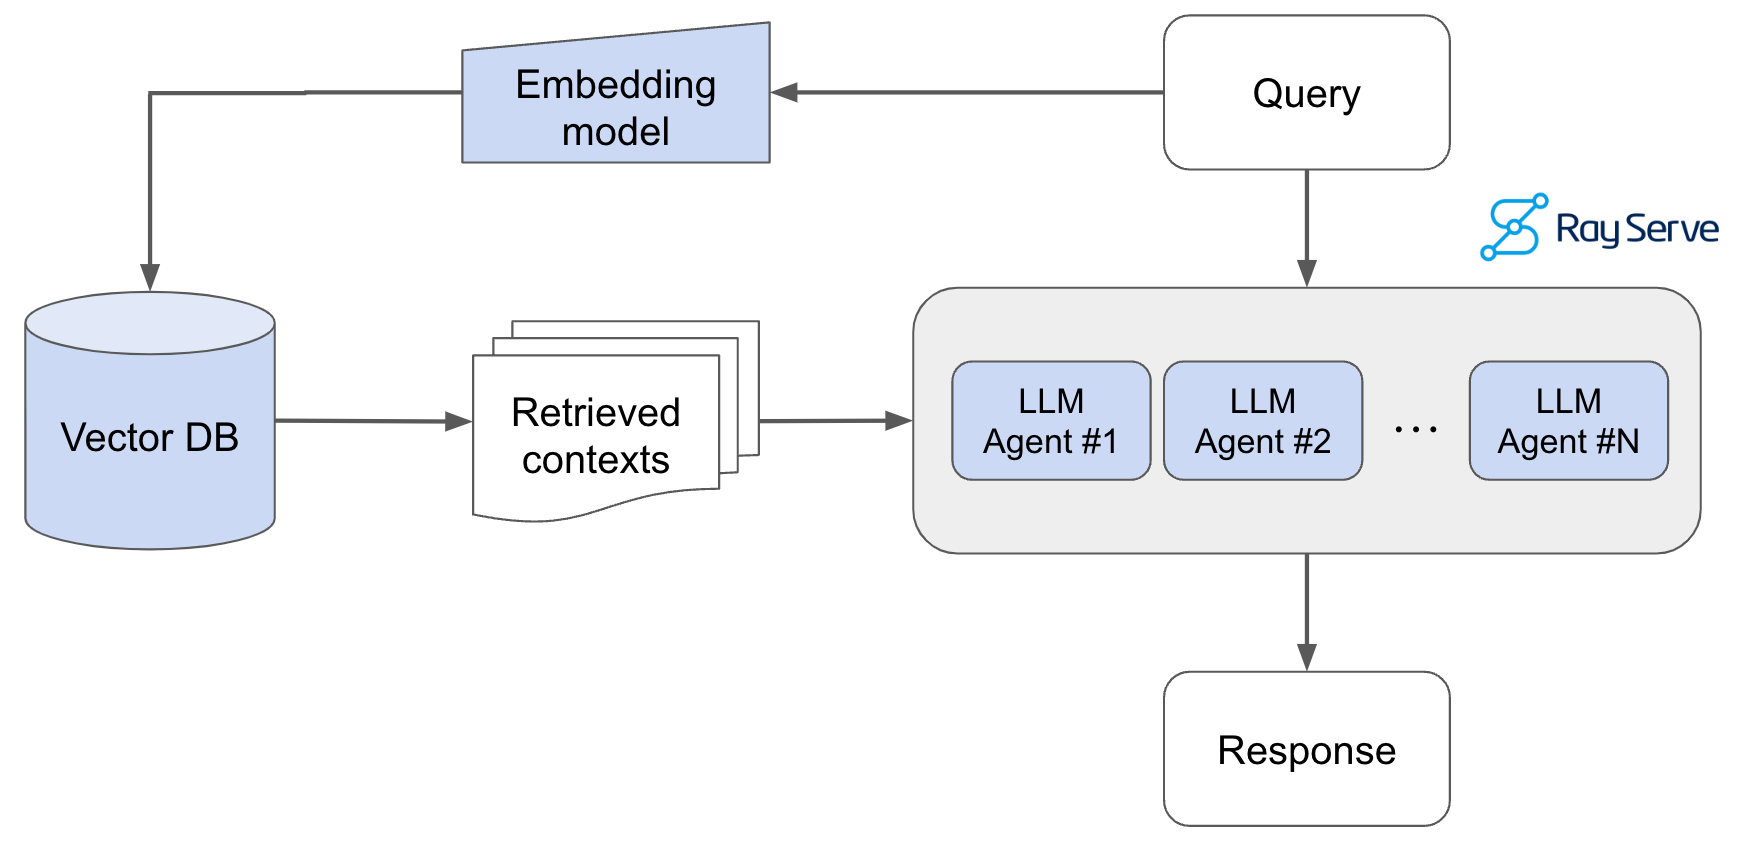
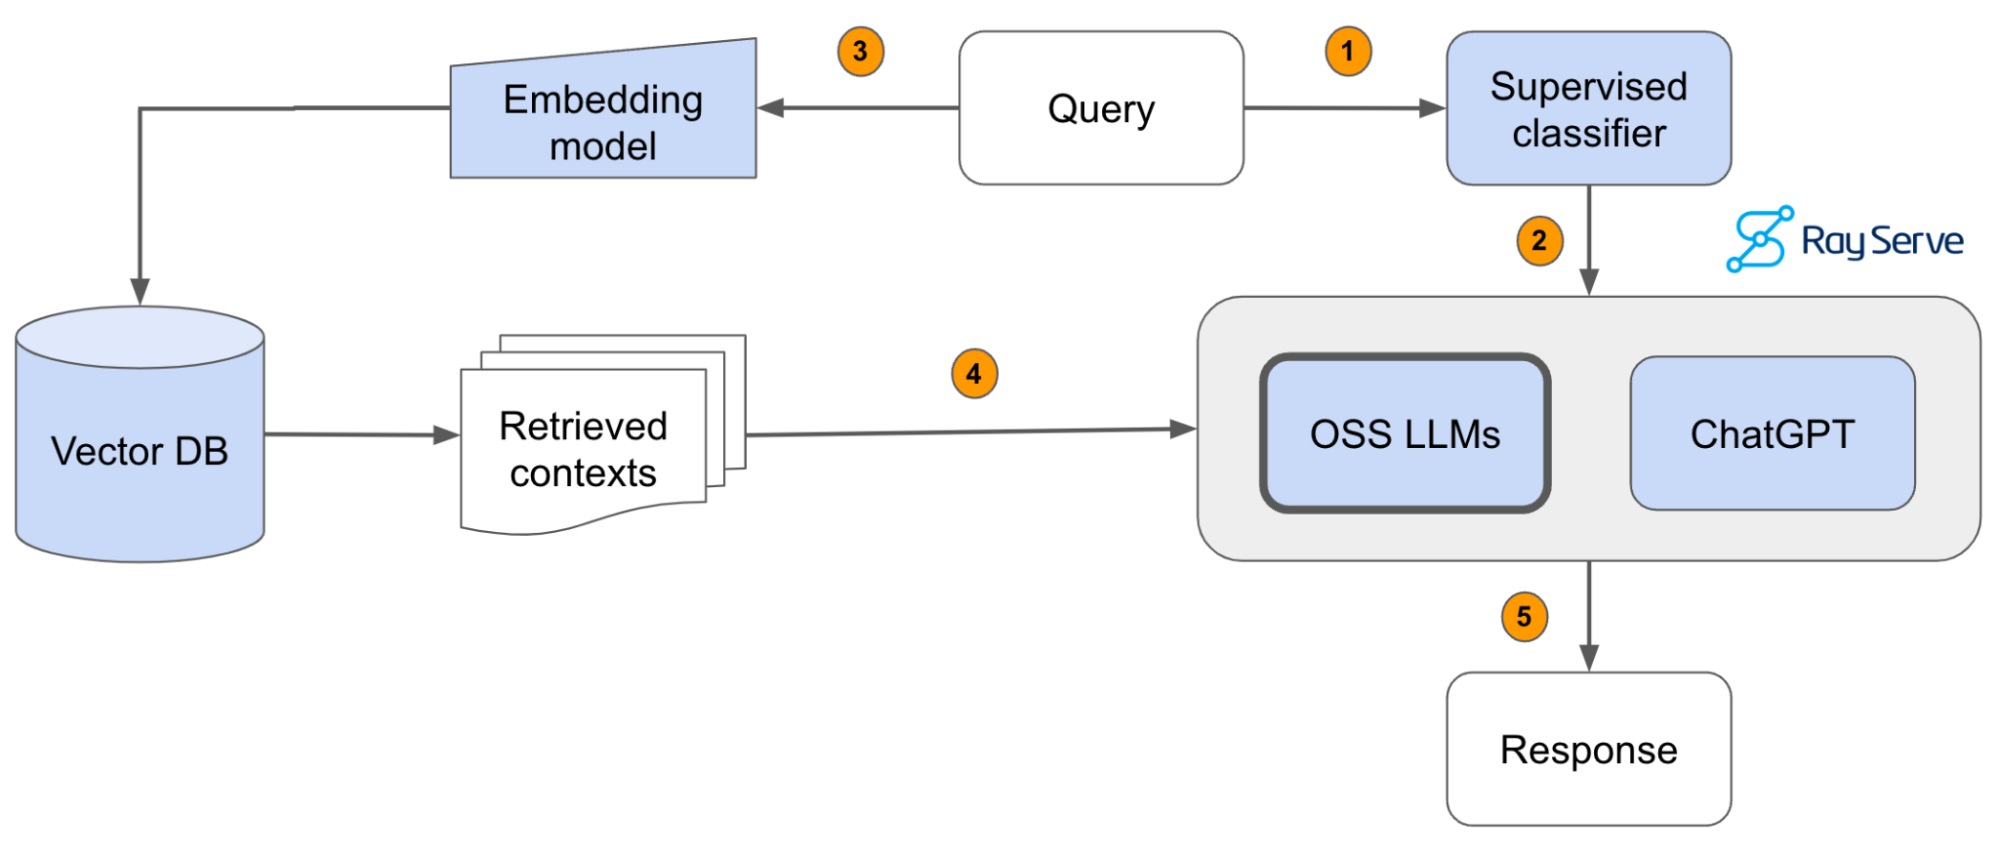
Building RAG-based LLM Applications for Production
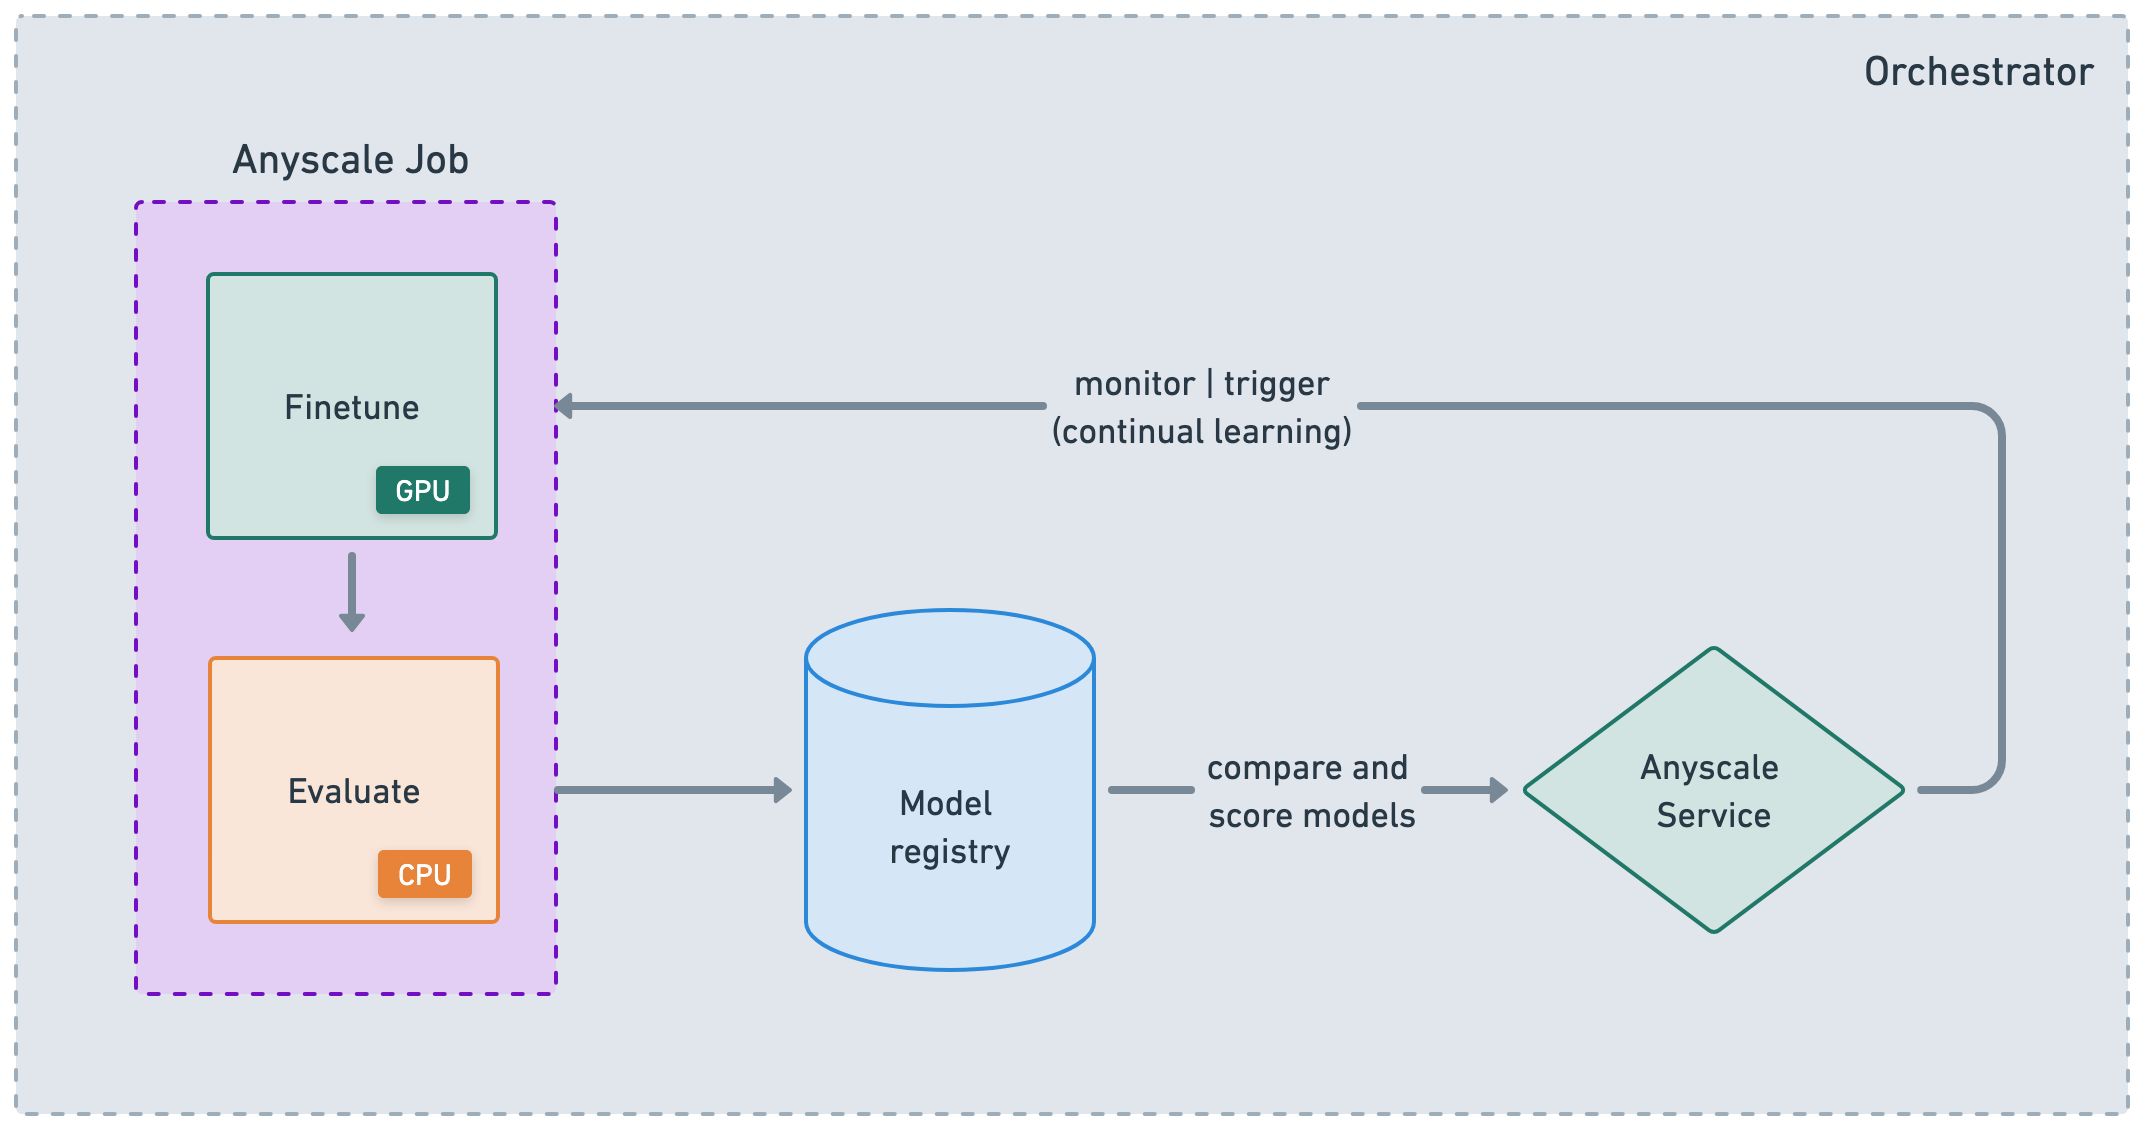
GitHub - anyscale/e2e-llm-workflows: Fine-tune an LLM to perform batch ...
Analyzing the Distributed Inference Process Using vLLM and Ray from the ...
Friday Night Lights: Rheinmetall Vario-Ray LLM | thefirearmblog.com
Ray Use Cases — Ray 2.56.0
Rheinmetall Vario-Ray LLM – Tiradores de Precisión GC
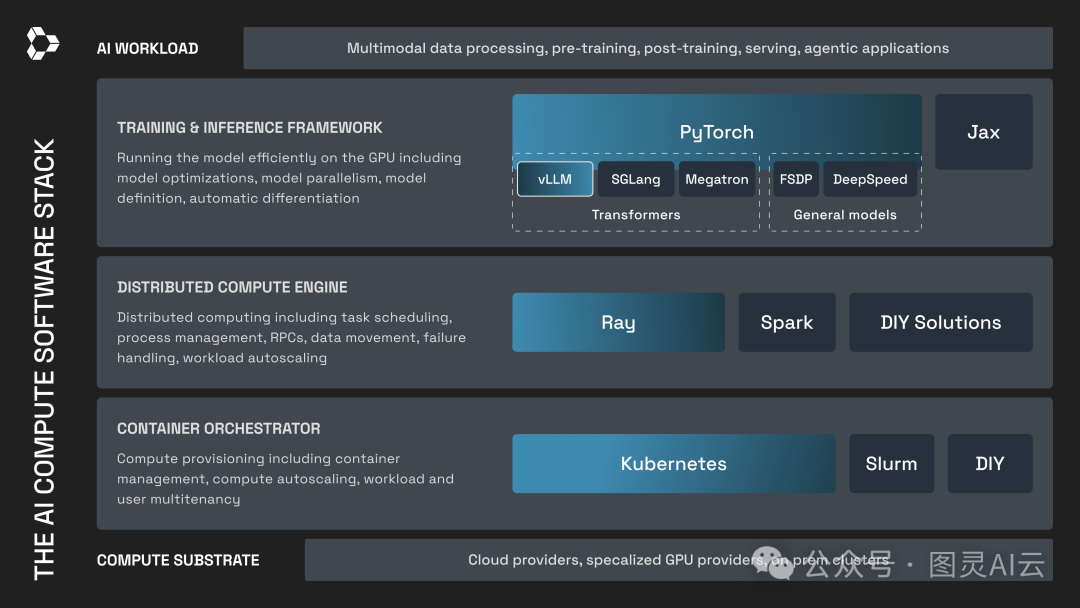
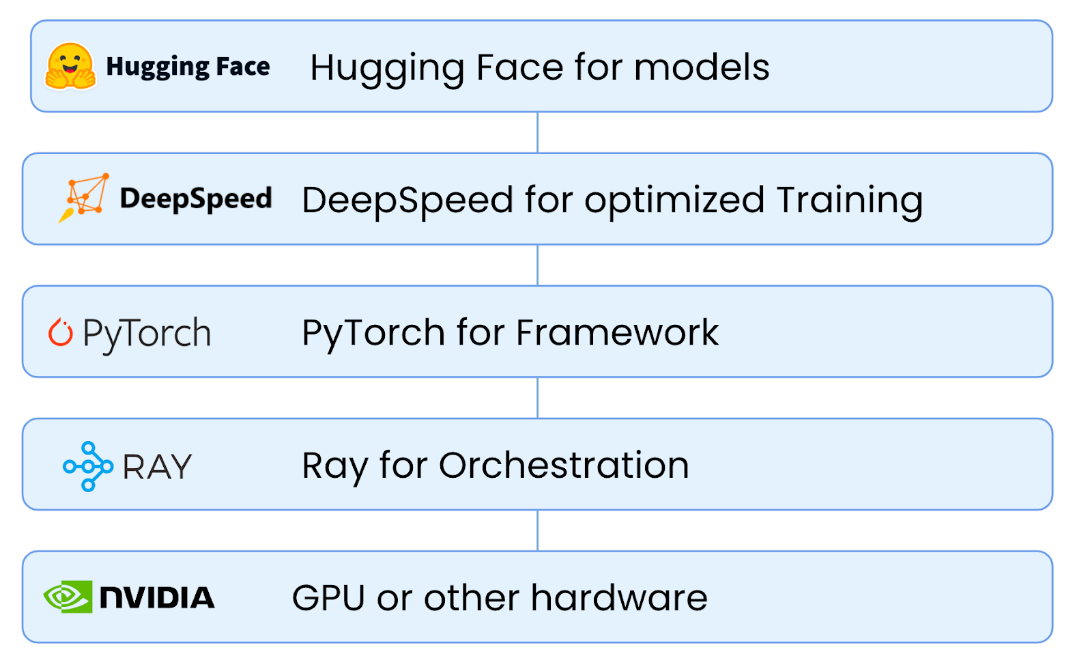
浅谈目前主流的LLM软件技术栈:Kubernetes + Ray + PyTorch + vLLM 的协同架构_vllm和ray如何协同-CSDN博客
Ray 用例 — Ray 2.53.0 - Ray AI 框架
Efficient Prompt Processing with Ray & vLLM
Day26 - LLMs on Ray - iT 邦幫忙::一起幫忙解決難題,拯救 IT 人的一天
Free Video: LLMs on Ray and LanceDB - Scaling Multimodal Pipelines and ...
LLM 发展趋势报告 (Ray1012) — ClawHub
Performance Monitoring in LLM Inference | by Sakhamuri Bandhavi | Medium
你聽過 LLM、RAG、Prompt 嗎?一文帶你看懂生成式 AI 常見技術詞彙 | 是 Ray 不是 Array
LLM Development Knowledge Sharing - Speaker Deck
R2F: Repurposing Ray Frontiers for LLM-free Object Navigation | AI ...
GitHub - ray-project/llm-numbers: Numbers every LLM developer should know
AI agents on Ray Serve: Single to multi-agent architecture | Anyscale
Cloudera Machine Learning で Ray を実行し、膨大な計算処理を必要とするLLMを強化 | ブログ | Cloudera
GitHub - daisysong76/ray_llm-vlm: self projects for practicing ray LLM/VLM
Free Video: How to Build an LLM Query Engine in 10 Minutes - LlamaIndex ...
Free Video: Efficient LLM Deployment: A Unified Approach with Ray, VLLM ...
GitHub - sanyaade-teachings/e2e-llm-workflows-ray: Fine-tune an LLM to ...
Productionizing open source LLMs with LangChain & Ray
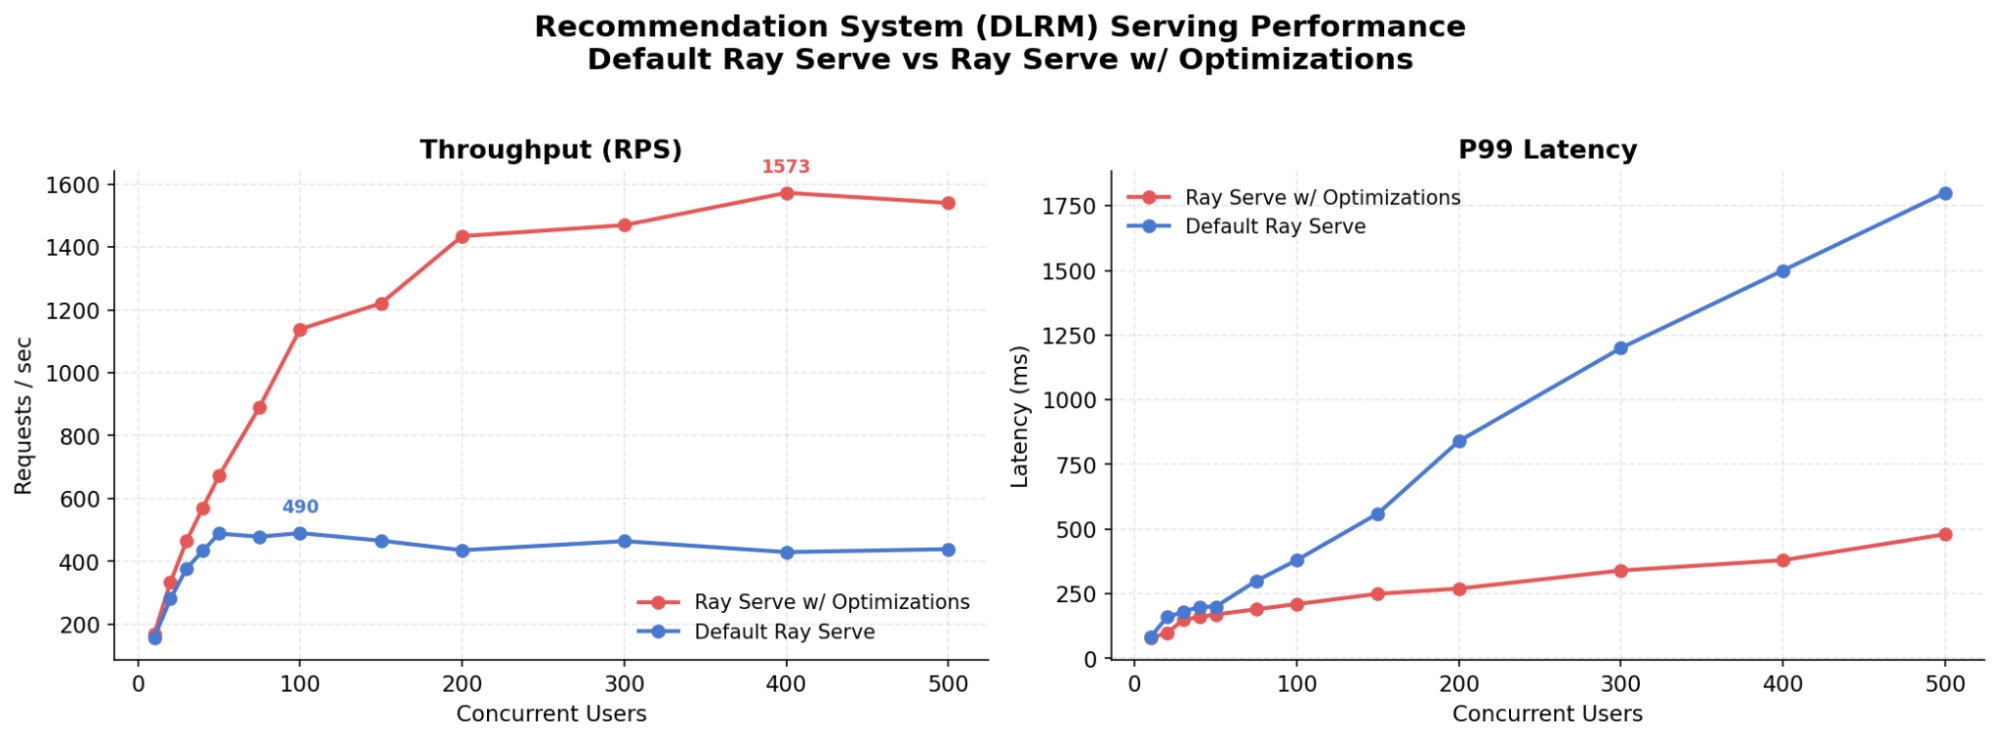
Major upgrades to Ray Serve: Online Inference with 88% lower latency ...
Running Phi 3 with vLLM and Ray Serve
Day27 - LLMs on Ray (踩雷?) - iT 邦幫忙::一起幫忙解決難題,拯救 IT 人的一天
Building a distributed AI system: How to set up Ray and vLLM on Mac Minis
GitHub - intel/llm-on-ray: Pretrain, finetune and serve LLMs on Intel ...
What is ray-llm? Features & Getting Started
github- ray-llm :Features,Alternatives | Toolerific
Running LLMs as Backend Services: 12 Open-source Free Options - a ...
GitHub - ray-project/llm-applications: A comprehensive guide to ...
github- llm-on-ray :Features,Alternatives | Toolerific
LLMOps Blueprint for Open Source LLMs
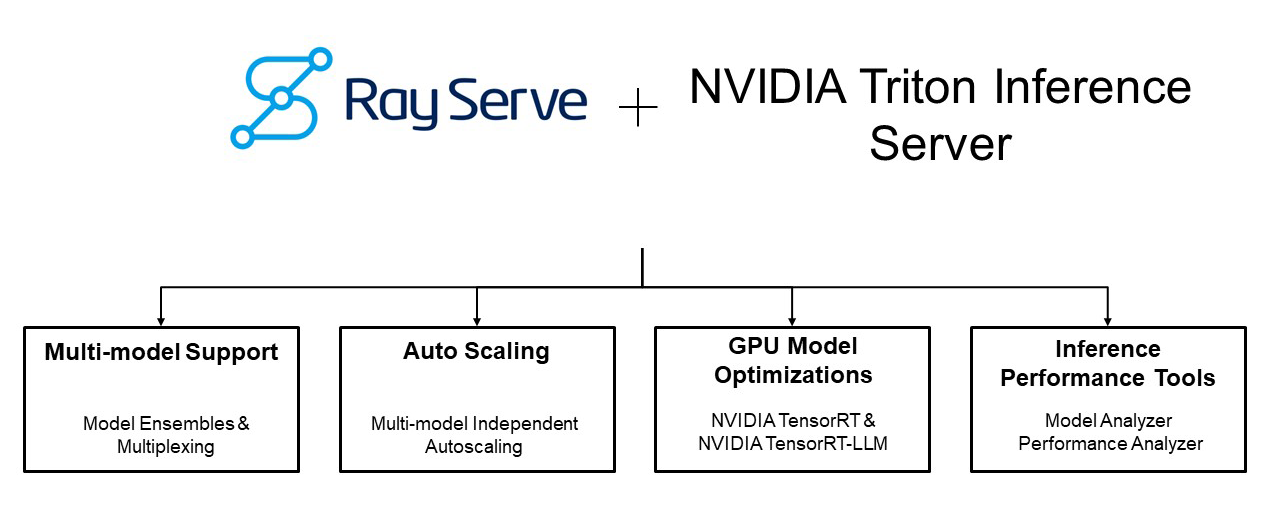
Low-latency Generative AI Model Serving with Ray, NVIDIA Triton ...
深入探讨Ray与LLM在强化学习框架设计中的应用!_streamrl asyncflow-CSDN博客
Blog | vLLM
ray-project_ray-llm/models/README.md at master · CongLeSolutionX/ray ...
vLLM Large Scale Serving: DeepSeek @ 2.2k tok/s/H200 with Wide-EP ...
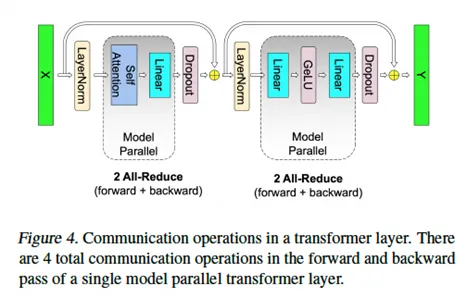
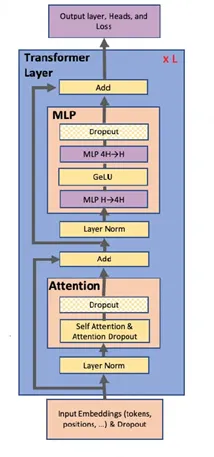
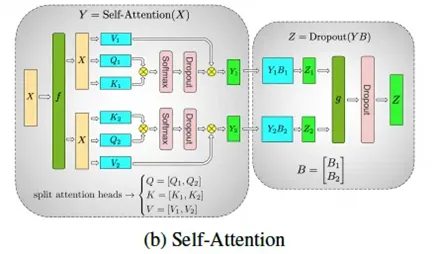
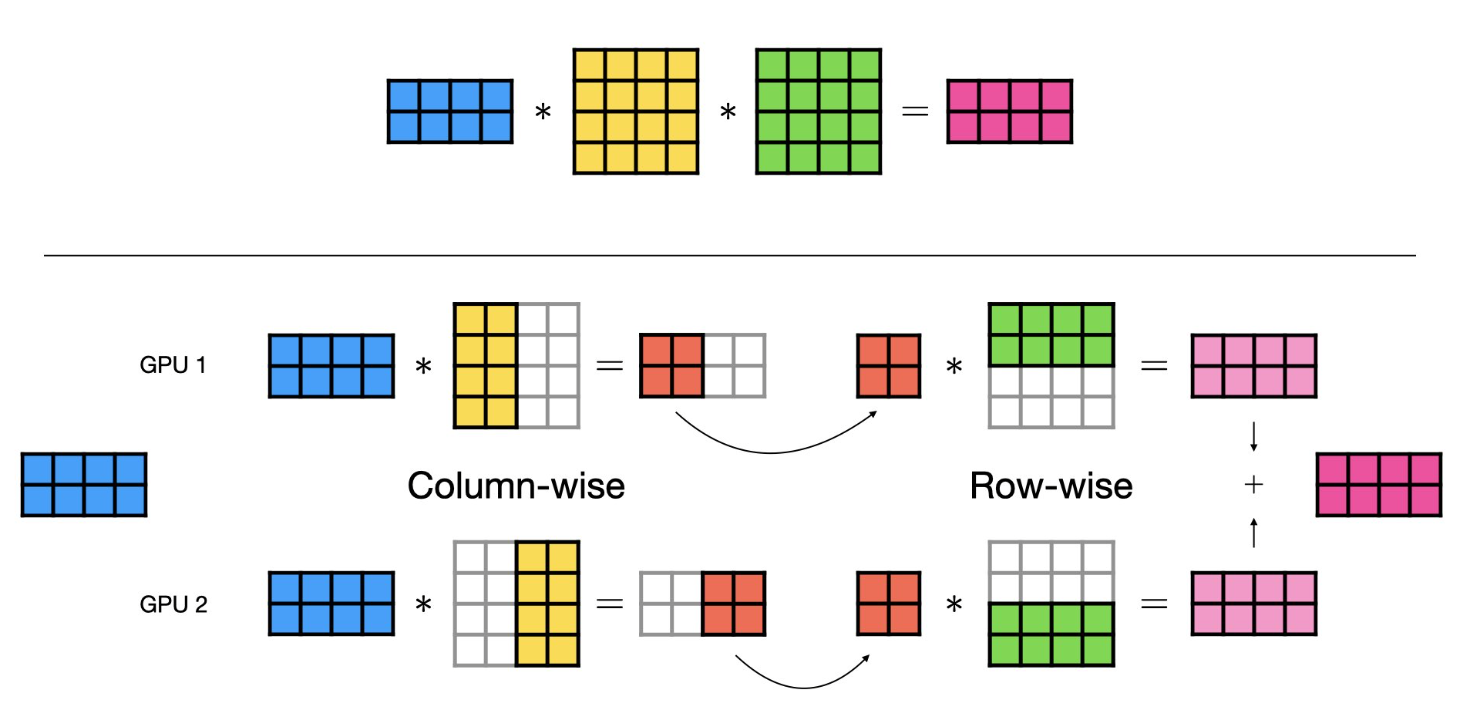
Combined Column- and Row-wise Parallelism:
开源平台Ray加速LLM模型训练部署_ray 模型训练-CSDN博客
基于Ray和vLLM实现大模型分布式推理 | Quantum Bit
LLM-VarioRay | Rheinmetall
ray-serve-llm-perf-examples/horizontal_scaling at master · anyscale/ray ...
ray-llm by ray-project - SourcePulse
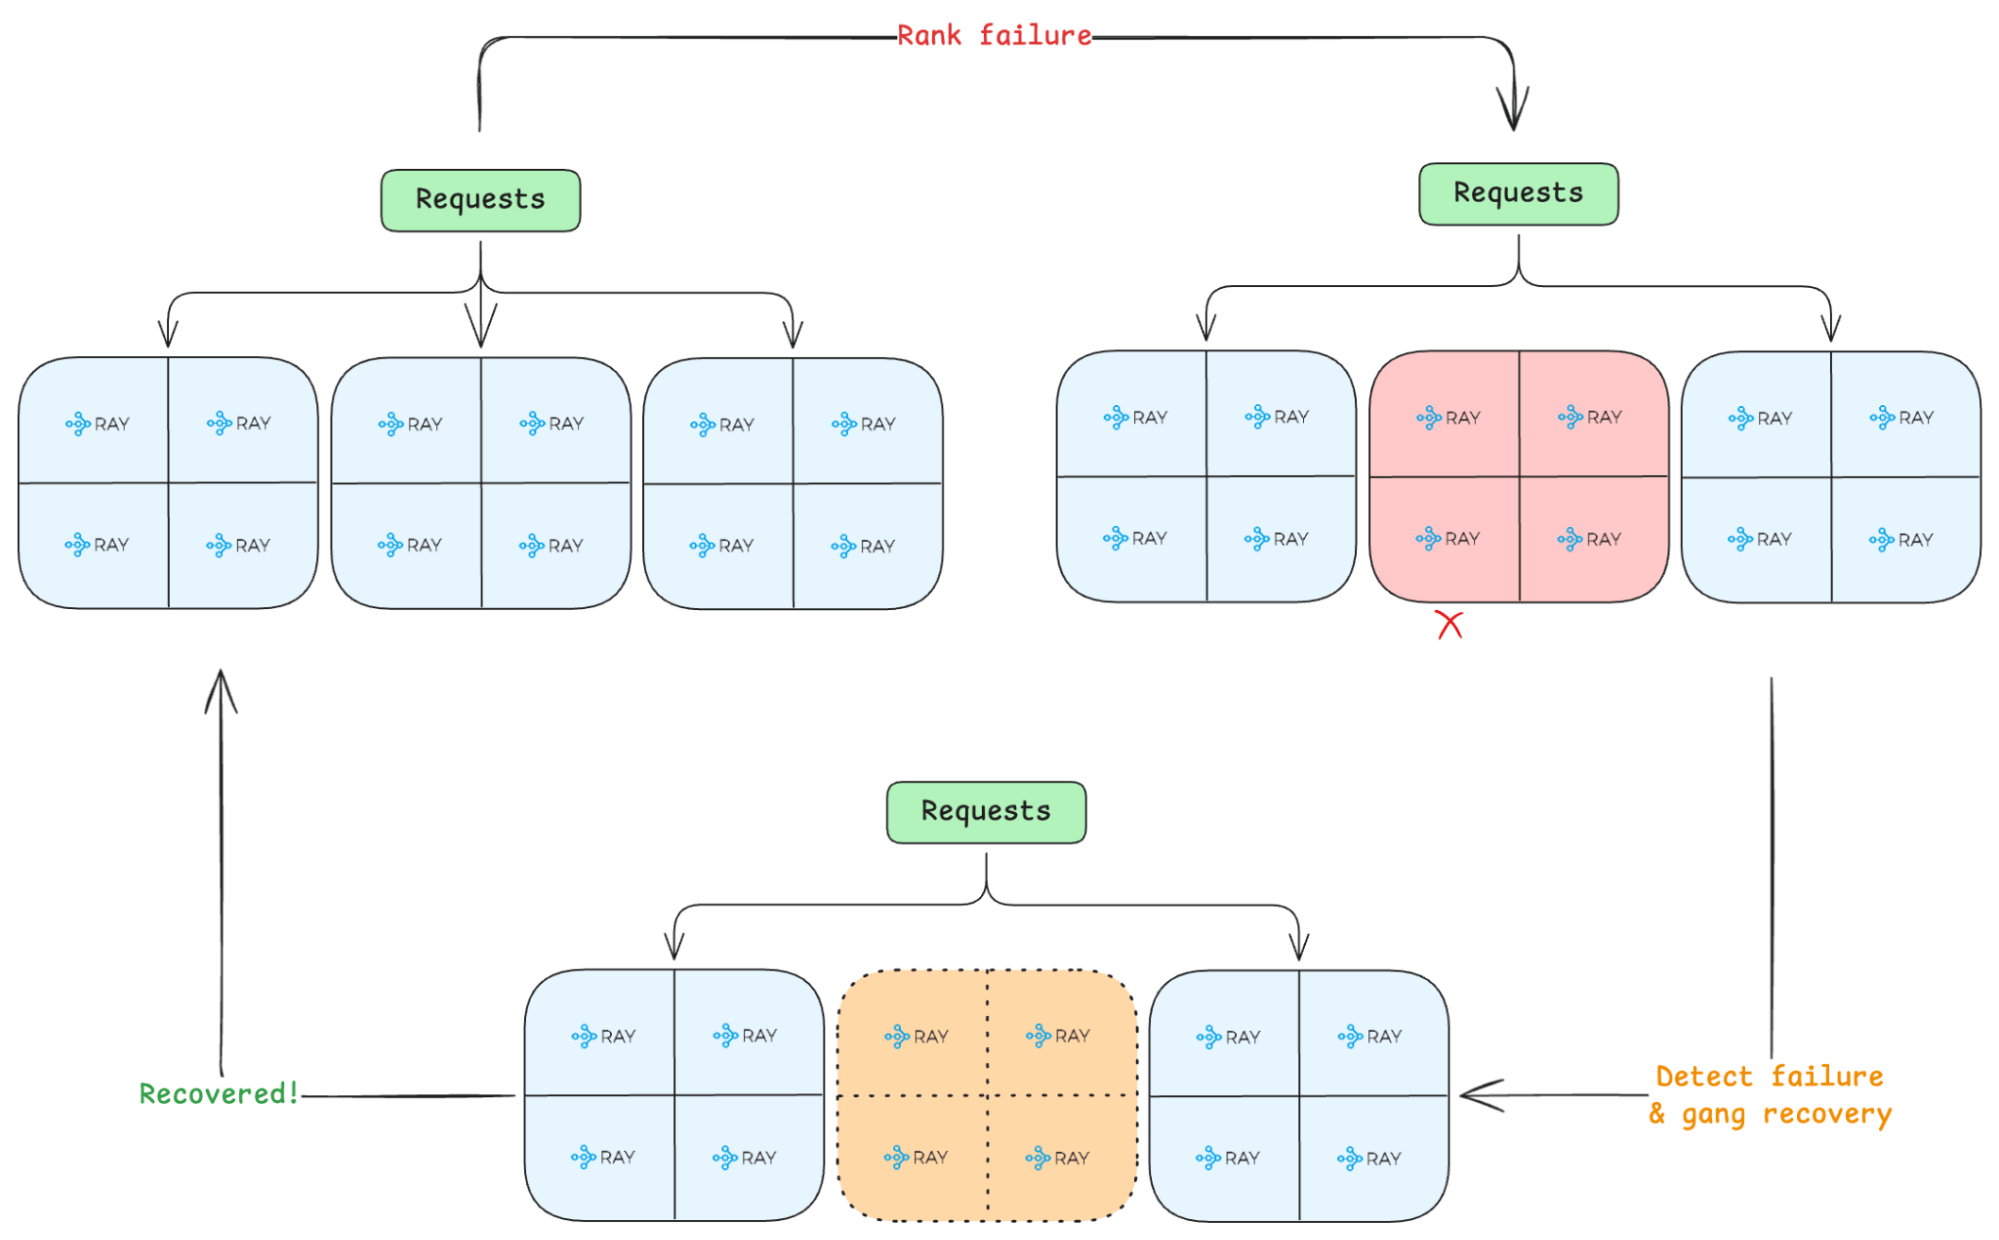
Announcing DP Group Fault Tolerance for vLLM WideEP Deployments with ...
在Ray集群中使用vLLM部署LLM模型并集成Prometheus和Grafana进行指标观测的实践 - zhaojie10 - 博客园
Row-wise Parallelism:
Technologies | Atomic Loops
Llama-3-8B with vLLM on Inferentia2 | AI on EKS